科技 · 实用指南
修正 Trakt 电影导入记录中的错误观看日期
保留电影的已看状态,将选定的错误日期改为 Unknown。先检查能否撤销准确对应的导入批次;否则逐条确认观看记录,验证新记录后再删除旧记录。
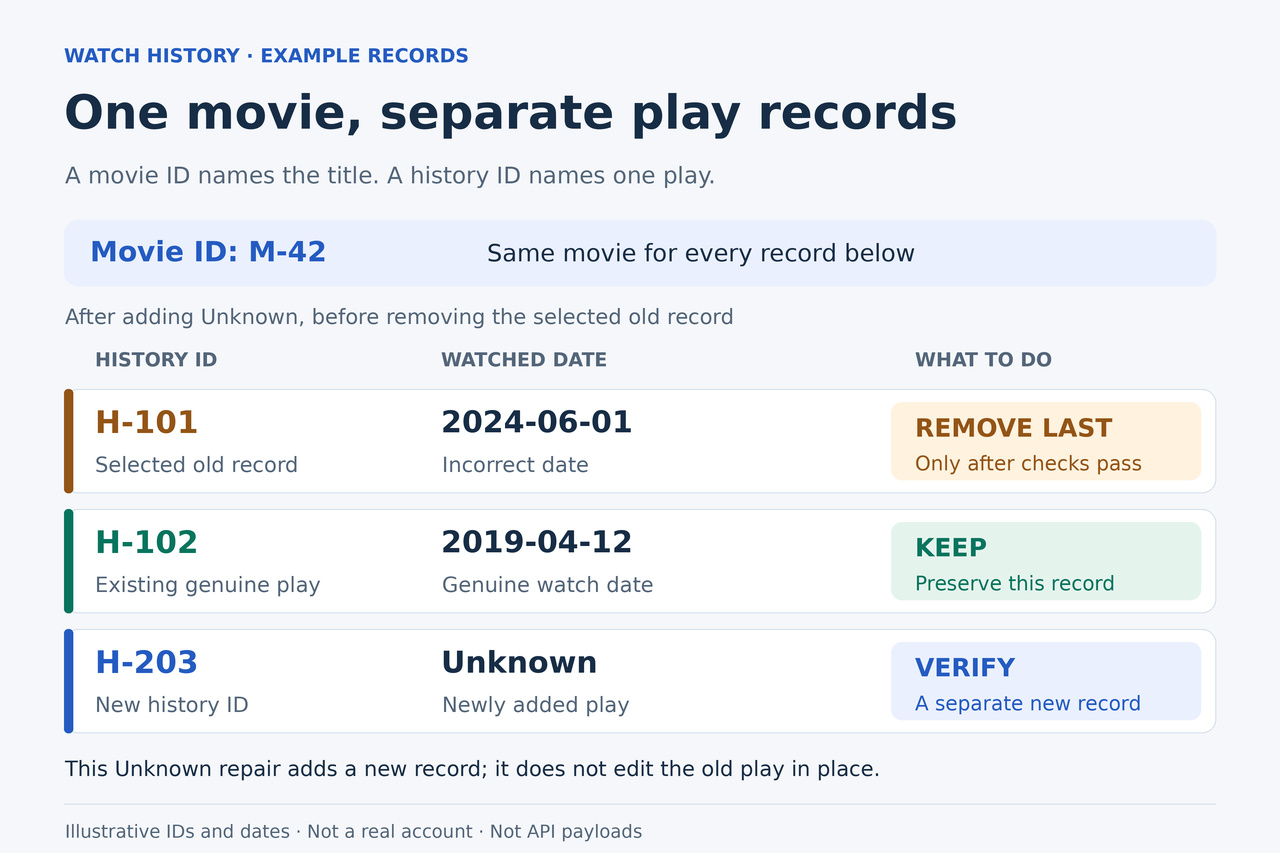
如果以前从 IMDb 或 Letterboxd 导入的数据,让许多电影看起来像是在同一天看完的,Trakt 的 Unknown(日期不详)可以保留你看过这些电影的事实,而不虚构观看日期。Unknown 记录仍计入观看总次数,但不计入按日期统计的图表。只添加 Unknown,并不会删除原来日期错误的那条观看记录。
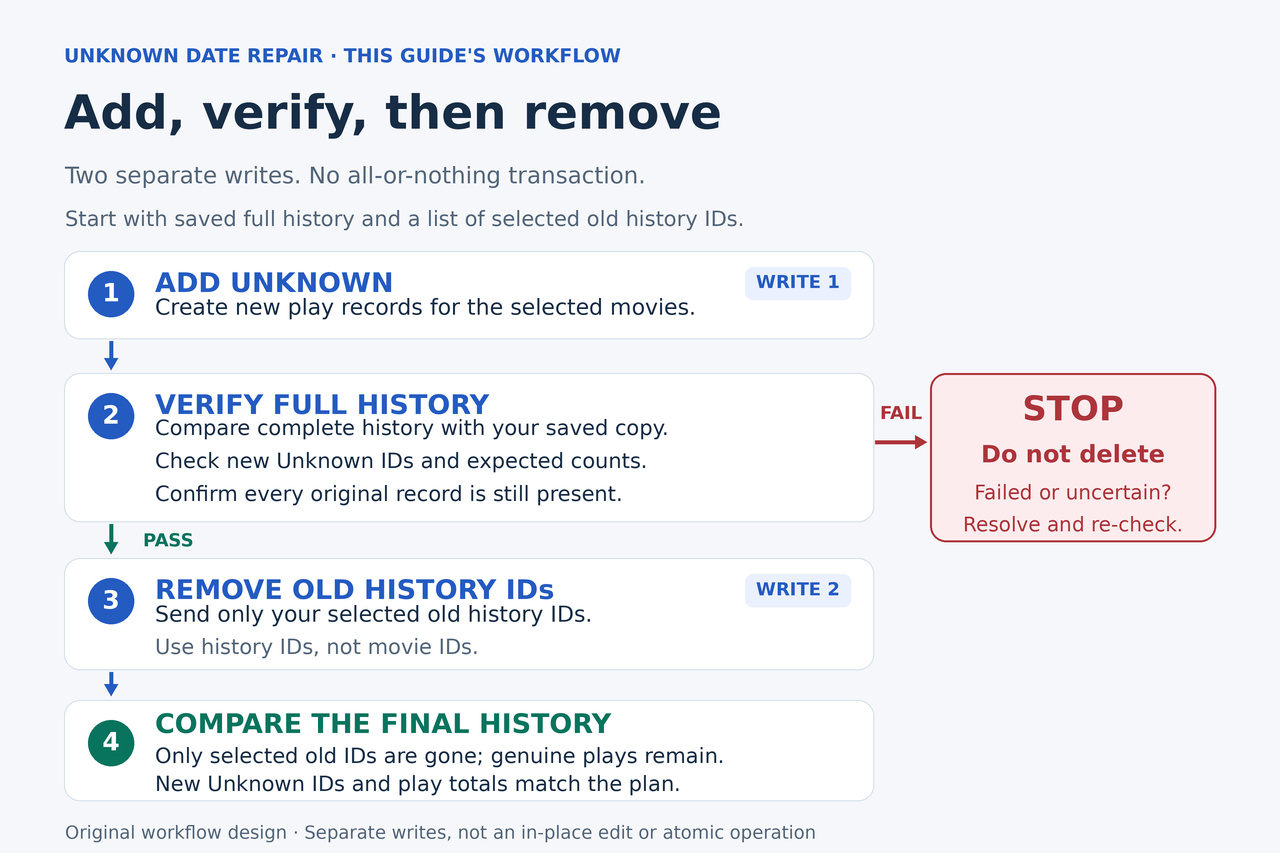
先检查是否能准确识别并撤销那一次错误导入。如果只想修正部分记录,本文提供完整的本地 Python 辅助程序:由你选出日期错误的观看记录,添加对应的 Unknown 新记录,核对结果,然后才删除选定的原观看记录 ID。辅助程序负责读取数据和准备文件;两次账户修改分别使用独立命令,由你检查后执行。
先确认哪些日期确实有误
把原始导入文件与新导出的 Trakt 备份一起保留。日期集中可以帮助寻找候选记录,但不能证明那一天的每次观看都是错误的。核对电影、来源记录以及你自己的记忆,保留同一天真实发生的观看。
Letterboxd 区分“曾经看过”与在 Diary 中登记某次具体观看。来源文件里的 Date 列不一定就是观看日期。如果有可信的观影日记日期,应保留它供按真实日期修正时使用;本批处理只针对真实日期未知的记录。
每个计划中,每部电影最多选择一条日期错误的观看记录。保留日期正确的重看记录。如果所选电影已经有 Unknown,应先停下来判断各条记录实际代表什么。本程序不会合并这些记录,也不承诺将多次日期不详的重看分别保留下来。
检查能否撤销准确对应的导入批次
Trakt 文档提供 GET /users/syncs/import 来列出导入同步记录,GET /users/syncs/ID 来查看某一条,以及 DELETE /users/syncs/ID 来撤销它。sync ID 标识一次导入操作,既不是电影 ID,也不是观看记录 ID。查找较早的导入时,要读取返回的全部分页。
只有当该记录能够可靠地对应到目标导入,而且你确实希望撤销整个批次时,才使用这一替代方案。撤销可能影响该批导入的观看记录、评分、暂停进度、Watchlist 和收藏。日期相同或数量接近都不足以证明对应关系。如果现有信息无法确认批次,就不要动它,改用下文的选择性修正。
不要假设每一次旧文件导入都能找到对应的同步记录,或在当前界面中找到撤销按钮。如果撤销了已确认的批次,应重新读取结果,根据原始来源准备修正后的输入,预览匹配结果和所选数据类型,再核对重新导入的结果。之后若仍需选择性修正,必须以撤销后的最新数据作为基线。
准备访问权限、备份和私有工作目录
使用 Bash、Python 3.10 或更高版本,以及 curl 7.76.0 或更高版本。按照下方链接中的最新官方说明,通过你自己的合规 Trakt 应用获取访问权限,并授权你自己的账户。注册应用需要已验证的 GitHub 连接和可用的应用名额,具体账户限制和审批要求以实际结果为准。本文不假设存在固定的免费额度,也不假设所有用户都必须订阅 VIP。
使用辅助程序前,按照 Trakt 的必需请求头和 OAuth 文档,准备一份本地请求头文件。文件必须包含 Authorization、trakt-api-key、trakt-api-version、Content-Type 和 User-Agent 五个字段,每行一个;API 版本设为 2,内容类型使用 JSON。填入你自己的已授权值,妥善保管,不要把文件内容粘贴到本站。辅助程序只导入这份已有文件,不会替你注册应用或创建授权。
当前 OAuth 主机是 auth.trakt.tv,下方数据请求使用 api.trakt.tv。如果采用设备授权,应遵守返回的轮询间隔和有效期。同一批处理始终使用同一份有效凭据文件,因为保存的快照与它绑定。如果访问权限在中途过期,或文件发生变化,应停止并保留本批文件;本程序不能把已经执行一部分的批次迁移到新凭据。
进行写入前,先导出账户数据。当前 JSON ZIP 中,单次观看记录位于 watched-history.json 或编号为 watched-history-N.json 的文件里;watched-movies.json 是汇总数据。检查导出结果,以及可能存在的 _errors.json;ZIP 下载成功不代表内容完整。涉及所需信息的导出失败解决后,才能把它视为可用备份。
暂停自动记录观看的程序和自动导入,并在核验完成前避免修改观看记录、评分或 Watchlist。为本批创建一个新的本地空目录,在该目录中打开 Bash。官方导出备份另行保存。API 分页读取不是一次原子化账户快照;暂停其他写入并检查全部分页可以减少错误,但不能让 API 操作变成事务。
安装辅助程序,再完整读取基线数据
文末“完整本地辅助程序”一节包含一条完整的源码写出命令。将整条命令复制到空工作目录中的 Bash 执行,它只在本地创建 trakt_repair.py,不发送 API 请求,也不会覆盖已有同名文件。运行辅助程序前,先打开生成的可读 Python 文件检查。所有语言版本的源码注释、提示和命令均保留英文。
使用按照官方说明准备的私有请求头文件初始化程序。把下方命令中的示例文件路径替换成实际本地路径;路径包含空格时应加引号。后续命令始终在同一工作目录中执行。导入的凭据和工作数据作为私有文件保存在 trakt-repair 下。
python3 trakt_repair.py init trakt-headers.txt
读取基线。此命令只通过已授权 GET 请求获取电影观看记录、电影评分和电影 Watchlist,保存原始响应字节、分页信息以及合并后的完整 JSON 文件。
python3 trakt_repair.py fetch before
只有程序报告快照完整后,才能继续。采集器使用返回的页数、实际每页条数和总条数,并再次检查第一页。缺少分页信息、某页条数不足、ID 重复、电影数据结构异常或观察到数据变化,都会使该快照不可用。不要删除 INCOMPLETE 来强行继续。解决读取失败后,用新的快照名称重新获取,并在后续 preview 和 plan 命令中使用这个新名称。
从完整基线生成审核 CSV。Python 保留原始大整数 ID;审核文件使用 h:、m:、t: 和 at: 前缀,让表格软件把标识符、片名和时间戳作为文本处理。
python3 trakt_repair.py preview before
选择错误记录并检查处理计划
打开 trakt-repair/before-review.csv。只在自己已确认日期有误的观看记录行中,将 choose 列填写为完全一致的 YES,然后保存为 UTF-8 CSV。其他所有单元格和前缀都不要改动。文件中的时间戳来自 API,Trakt 界面的 Today 标签可能使用不同的显示时区。创建计划时,程序会再保存一份所选 CSV 的副本。
python3 trakt_repair.py plan before trakt-repair/before-review.csv
计划会根据原始基线核对每个选定的观看记录 ID,并检查电影、片名和原时间戳。所选电影重复或已经有 Unknown 时,程序会拒绝继续。它会显示拟替换的记录,并要求输入完全一致的 YES 后才保存计划。Trakt 已公布按分钟归一化时间戳、按项目与时间组合去重的行为;修改秒数不能用于保留多条独立的日期不详重看记录。
如果所选电影还在内置 Watchlist 中,程序会显示这些电影 ID,并单独询问是否接受它们被移出清单。Trakt 可能在标记已看时自动移除待看项目;本次核对的来源没有确认 Unknown 可豁免此行为。只有接受这一结果时,才输入 YES, REMOVE FROM WATCHLIST。否则应停止、排除这些电影,再重新审核。核验范围是 Watchlist 中有哪些电影,不包括保留备注、排序或原加入日期。
用文本编辑器检查 trakt-repair/plan.json 和 trakt-repair/add.json。添加请求使用电影 ID,并将 watched_at 设为字面字符串 unknown。不要改成 null、省略此值,或填入虚构的旧日期。此时尚未生成删除请求。先用一条已确认错误的记录试运行;通过最终核验后,下一批应另建新的空父工作目录,重新获取基线,再处理较大的选择范围。已有计划不会被覆盖。
添加 Unknown,再验证新记录
下方命令是第一次账户修改。检查 add.json 后,只执行一次,并保存响应正文和响应头。每条写入命令都要求响应文件名尚未使用,关闭 curl 的隐式配置,且没有自动重试或重定向选项。如果因为响应文件已存在而拒绝执行,应检查已保存状态,而不是删除文件后重发写入。
test ! -e trakt-repair/add-response.json && test ! -e trakt-repair/add-response-headers.txt && curl -q --fail-with-body --silent --show-error --request POST --header @trakt-repair/auth.headers --data-binary @trakt-repair/add.json --dump-header trakt-repair/add-response-headers.txt --output trakt-repair/add-response.json --write-out 'HTTP %{http_code}\n' https://api.trakt.tv/sync/history
请求返回后,即使出现错误或结果不确定,也应重新完整读取一份快照,并运行中间核验。仅凭 added 数量或 HTTP 成功状态,无法确定当前实际存在的观看记录 ID。
python3 trakt_repair.py fetch after-add
python3 trakt_repair.py verify-add after-add
核验要求每部所选电影恰好新增一个 Unknown 观看记录 ID,同时每一条原电影观看记录仍然存在,电影身份、归一化到分钟的时间戳和 action 均一致。电影评分及评分时间戳必须不变。只允许计划中已经接受的 Watchlist 移除;出现新增项目或其他电影丢失都会停止。
读回数据时,Unknown 对应精确的 UTC 时刻 1970-01-01T00:00:00Z;等价的 .000Z 写法表示同一时刻。程序比较解析后的时刻,不会把一整天或一整年都视为 Unknown。请求仍发送字面字符串 unknown。程序会把已验证的新 ID 与原先选定的旧 ID 分开保存。
只有通过中间核验后,才会生成 trakt-repair/add-verified.json 和 trakt-repair/remove.json。检查后一个文件:顶层 ids 数组必须只包含你选定的原观看记录 ID。movies 数组的删除范围更广,不能用它替换 ids。新增的 Unknown ID 也绝不能出现在此删除请求中。
此时,每部所选电影会暂时多出一次观看。流程先验证替代记录,再删除旧记录,避免主动制造一次观看都没有的中间状态。但这依然是两个独立 API 写入,可能产生账户侧影响,并不是直接修改原记录的日期。
只删除旧 ID,并核对是否完成
只有中间核验通过、并检查 remove.json 后,才执行下方第二次账户修改命令。保存响应,包括 deleted 和 not_found 信息。
test ! -e trakt-repair/remove-response.json && test ! -e trakt-repair/remove-response-headers.txt && curl -q --fail-with-body --silent --show-error --request POST --header @trakt-repair/auth.headers --data-binary @trakt-repair/remove.json --dump-header trakt-repair/remove-response-headers.txt --output trakt-repair/remove-response.json --write-out 'HTTP %{http_code}\n' https://api.trakt.tv/sync/history/remove
重新获取完整快照,并检查最终结果:
python3 trakt_repair.py fetch final
python3 trakt_repair.py verify-final final
成功状态应等于原电影观看记录集合减去所选旧 ID,再加上此前核验确认的新 Unknown ID。每条未选中的原记录和每条替代记录,都必须保留预期的电影身份、归一化时间戳和 action。电影评分必须不变,电影 Watchlist 的成员必须与添加完成后的快照一致。仅有总数一致不能通过。
满足这些条件时,程序会写出 final-verified-final.json。每条所选记录都以一条新记录替换后,电影观看总次数恢复到基线数量,真实的带日期重看记录仍然存在。还应在 Trakt 中打开几部已修正电影,单独做一次界面检查:电影仍为已看,并有 Unknown 记录,而所选的错误日期已不在观看历史中。Unknown 按设计应排除在日期统计图表之外。
私下保留原始来源、官方导出、原始快照、所选 CSV、计划、请求、响应和核验文件。替代记录拥有新的观看记录 ID;本流程不会保留被删记录原有的 scrobble 或 check-in 身份。确认最终结果可以接受后,再恢复暂停的自动导入。
读取或添加中断时,保留已保存的阶段
读取失败不能证明基线或结果完整。遇到 HTTP 错误时,辅助程序会将响应状态、相关响应头和正文保存到带时间戳的 get-error 文件中,不会把请求凭据写进这些诊断文件。快照继续保留 INCOMPLETE。解决报告的问题后,换一个新快照名称重新读取,不要覆盖失败时的证据。
如果只观察到部分添加结果,verify-add 会写出 add-incomplete 报告,列明新增 Unknown ID 和仍缺少替代记录的电影,不会生成 remove.json。不要重发整份添加请求,也不要删除原记录。待此前请求结束后,用新名称获取较晚的快照,再针对该名称运行 verify-add。如果这时完整的预期结果已经出现,便可从核验通过的阶段继续。
本辅助程序不会自动生成针对缺失添加项的补发请求。如果结果仍不完整,应保留报告并停止本次修正,或在重新核验后使用下文的放弃分支。出现意外新增记录、原记录丢失、评分变化或未接受的 Watchlist 变化时,需要先调查;不要修改快照清单文件(manifest)或删除核验条件来强行通过。
Trakt 文档规定,已授权写请求每秒一次,已授权 GET 请求每五分钟 500 次。出现 429 时,应遵守 Retry-After;其他应用可能共用账户限制。认证失败、应用审批、账户限制和无效数据属于不同错误。替换令牌不能解决所有 403、420、422 或 426 响应,而且本程序会把进行中的批次绑定到已有凭据文件。
删除只完成一部分时,仅重试仍存在的选定旧 ID
删除响应不确定时,应先获取新快照并运行 verify-final。如果所有应保留的记录都正确,仅部分选定的原 ID 仍存在,程序会生成只包含这些 ID 的 remaining-remove 文件,并停止,而不是报告完成。它不会为了让数量相符而删除某部电影的全部观看记录。
下例仅适用于 verify-final final 已生成 trakt-repair/remaining-remove-final.json 的情况。使用前先检查这个准确文件。如果快照名称不同,应使用程序实际报告的 remaining-remove 文件名,并为响应使用新的文件名。
test ! -e trakt-repair/remove-retry-response.json && test ! -e trakt-repair/remove-retry-response-headers.txt && curl -q --fail-with-body --silent --show-error --request POST --header @trakt-repair/auth.headers --data-binary @trakt-repair/remaining-remove-final.json --dump-header trakt-repair/remove-retry-response-headers.txt --output trakt-repair/remove-retry-response.json --write-out 'HTTP %{http_code}\n' https://api.trakt.tv/sync/history/remove
随后再次获取新快照,检查同一组最终条件。删除恢复过程中不要重新执行添加请求。
python3 trakt_repair.py fetch final-2
python3 trakt_repair.py verify-final final-2
可选:在删除原记录前放弃新增的 Unknown
这一分支只用于在所有原观看记录都还存在时,放弃已经添加的新记录。等待未结束的请求完成,并保持其他写入暂停。程序必须确认,新增内容仅限于所选电影的 Unknown,每部最多一条,原观看记录和评分都完整保留。此前已接受的 Watchlist 移除可能仍然存在;这不是完整账户回滚。
python3 trakt_repair.py fetch undo-check
python3 trakt_repair.py prepare-undo-add undo-check
只有程序生成 undo-add-undo-check.json 后,才检查该文件,并确认其中只有新添加的 Unknown 观看记录 ID,绝不能含原 ID。下一条命令会明确删除这些新记录。如果程序拒绝继续,应保留文件并调查,不要自行构造删除范围更广的请求。
test ! -e trakt-repair/undo-add-response.json && test ! -e trakt-repair/undo-add-response-headers.txt && curl -q --fail-with-body --silent --show-error --request POST --header @trakt-repair/auth.headers --data-binary @trakt-repair/undo-add-undo-check.json --dump-header trakt-repair/undo-add-response-headers.txt --output trakt-repair/undo-add-response.json --write-out 'HTTP %{http_code}\n' https://api.trakt.tv/sync/history/remove
再次读取数据,核验原电影观看记录和评分均存在。对于此前已接受的 Watchlist 丢失,应另外检查。
python3 trakt_repair.py fetch undone
python3 trakt_repair.py verify-undo undone
放弃完成后,将本批结束封存,以后不要再运行它的旧 add.json 或 remove.json。任何新尝试都必须使用新的空工作目录和新基线。如果快照无法准确证明发生了什么,应保留仍存在的记录,用已移除敏感信息的计划寻求帮助,不要猜测该删除哪些 ID。
完整本地辅助程序
将下一段的完整命令作为一条 Bash 命令复制执行。它只写出可读源码文件,不运行辅助程序,也不连接 Trakt。之后打开 trakt_repair.py 检查,再返回“安装辅助程序,再完整读取基线数据”一节。保留直引号和反斜杠,不要翻译这条命令。
python3 -c 'from pathlib import Path; import hashlib,sys; p=Path("trakt_repair.py"); source="#!/usr/bin/env python3\n\"\"\"Movie-history repair helper: local files and authenticated GET requests only.\n\nThis program NEVER sends POST, DELETE or PUT requests. Inspect its generated\nJSON, then use separate explicit curl commands. Python 3.10+; Bash examples.\nAPI response contracts were checked against the Trakt authors'"'"' published code.\nNo live account or device was used to test this helper. Pause other imports,\nscrobblers and history edits until the final check. Pagination is not atomic.\n\"\"\"\nimport argparse\nimport csv\nimport datetime as dt\nimport hashlib\nimport io\nimport json\nimport os\nfrom pathlib import Path\nimport re\nimport sys\nimport time\nimport urllib.error\nimport urllib.parse\nimport urllib.request\n\nROOT = Path(\"trakt-repair\")\nAPI = \"https://api.trakt.tv\"\nENDPOINTS = {\"history\": \"/users/me/history/movies\", \"ratings\": \"/users/me/ratings/movies\", \"watchlist\": \"/users/me/watchlist/movies/rank\"}\nEPOCH = dt.datetime(1970, 1, 1, tzinfo=dt.timezone.utc)\nLAST_GET = 0.0\n\n\ndef check(ok, why):\n if not ok:\n raise ValueError(why)\n\n\ndef sha(data):\n return hashlib.sha256(data).hexdigest()\n\n\ndef encoded(value):\n return (json.dumps(value, ensure_ascii=False, indent=2) + \"\\n\").encode(\"utf-8\")\n\n\ndef read_json(path):\n return json.loads(path.read_bytes())\n\n\ndef write_new(path, data):\n with path.open(\"xb\") as f:\n f.write(data)\n\n\ndef write_same(path, data):\n if path.exists():\n check(path.read_bytes() == data, \"Existing output differs; it will not be overwritten: \" + str(path))\n else:\n write_new(path, data)\n\n\ndef now():\n return dt.datetime.now(dt.timezone.utc).isoformat()\n\n\ndef number(v):\n return type(v) is int and 0 < v <= 9223372036854775807\n\n\ndef date(v):\n check(isinstance(v, str), \"Missing or non-string timestamp; null is not Unknown.\")\n d = dt.datetime.fromisoformat(v.replace(\"Z\", \"+00:00\"))\n check(d.tzinfo is not None, \"Timestamp has no timezone.\")\n return d.astimezone(dt.timezone.utc)\n\n\ndef mid(row):\n check(isinstance(row, dict) and row.get(\"type\") == \"movie\", \"Unexpected non-movie row.\")\n m = row.get(\"movie\")\n check(isinstance(m, dict) and isinstance(m.get(\"ids\"), dict), \"Missing/null movie: stop, do not skip it.\")\n i = m[\"ids\"].get(\"trakt\")\n check(number(i), \"Invalid Trakt movie ID.\")\n return i\n\n\ndef validate(kind, rows):\n check(isinstance(rows, list), \"Expected a JSON array.\")\n seen = set()\n for r in rows:\n movie = mid(r)\n if kind == \"history\":\n key = r.get(\"id\")\n check(number(key), \"Invalid history ID; require an exact positive int64.\")\n date(r.get(\"watched_at\"))\n check(isinstance(r.get(\"action\"), str) and bool(r[\"action\"]), \"Missing history action.\")\n else:\n key = movie\n if kind == \"ratings\":\n check(type(r.get(\"rating\")) is int and 1 <= r[\"rating\"] <= 10, \"Invalid rating.\")\n date(r.get(\"rated_at\"))\n elif kind == \"watchlist\":\n date(r.get(\"listed_at\"))\n else:\n raise ValueError(\"Unexpected dataset.\")\n check(key not in seen, \"Duplicate ID: incomplete or changing snapshot.\")\n seen.add(key)\n return rows\n\n\ndef signature(r):\n return (mid(r), date(r[\"watched_at\"]).replace(second=0, microsecond=0).isoformat(), r[\"action\"])\n\n\ndef hist(rows):\n return {r[\"id\"]: signature(r) for r in rows}\n\n\ndef ratings(rows):\n return {mid(r): (r[\"rating\"], date(r[\"rated_at\"]).isoformat()) for r in rows}\n\n\ndef watchlist(rows):\n return {mid(r) for r in rows}\n\n\ndef label(value):\n check(bool(re.fullmatch(r\"[a-z][a-z0-9_-]{0,40}\", value)), \"Use a short lowercase snapshot name, for example before or after-add.\")\n return value\n\n\ndef parse_headers(raw):\n text = raw.decode(\"ascii\")\n check(\"\\r\" not in text.replace(\"\\r\\n\", \"\"), \"Use LF or CRLF header lines, not a bare carriage return.\")\n lines = text.replace(\"\\r\\n\", \"\\n\").split(\"\\n\")\n if lines and lines[-1] == \"\":\n lines.pop()\n check(lines and all(lines), \"Empty header lines are not accepted.\")\n headers = {}\n for line in lines:\n check(not any(ord(c) < 32 or ord(c) == 127 for c in line), \"Folded lines and control characters are not accepted.\")\n name, separator, value = line.partition(\":\")\n check(separator and re.fullmatch(r\"[A-Za-z0-9-]+\", name), \"Malformed local header file; use one complete header per line.\")\n key = name.lower()\n check(key not in headers, \"Duplicate header name in local file.\")\n value = value.strip(\" \")\n check(value and not any(ord(c) < 32 or ord(c) == 127 for c in value), \"Header values must be nonempty and contain no control characters.\")\n headers[key] = value\n check(set(headers) == {\"authorization\", \"trakt-api-key\", \"trakt-api-version\", \"content-type\", \"user-agent\"}, \"The local file must contain exactly the five header names listed in this guide and Trakt'"'"'s authentication reference.\")\n check(headers[\"trakt-api-version\"] == \"2\", \"The API version header must be 2.\")\n # The reader prepares all values using the official authentication reference.\n # This helper does not create, infer, inspect a scheme, or refresh credentials.\n return headers\n\n\ndef auth():\n raw = (ROOT / \"auth.headers\").read_bytes()\n return parse_headers(raw), sha(raw)\n\n\ndef init(headers_file):\n raw = Path(headers_file).expanduser().read_bytes()\n parse_headers(raw)\n ROOT.mkdir(exist_ok=True, mode=0o700)\n check(not (ROOT / \"auth.headers\").exists(), \"Credentials already exist; do not change accounts within a repair batch.\")\n ROOT.chmod(0o700)\n write_new(ROOT / \"auth.headers\", raw)\n (ROOT / \"auth.headers\").chmod(0o600)\n print(\"Imported your existing complete header file byte-for-byte into a private local working directory. No authentication value was created or displayed. Keep both local copies private; do not share this directory.\")\n\n\ndef get(path, headers):\n global LAST_GET\n delay = 0.65 - (time.monotonic() - LAST_GET)\n if delay > 0:\n time.sleep(delay)\n LAST_GET = time.monotonic()\n request = urllib.request.Request(API + path, headers=headers, method=\"GET\")\n # No retry and no redirect: do not forward credentials to another location.\n class NoRedirect(urllib.request.HTTPRedirectHandler):\n def redirect_request(self, req, fp, code, msg, response_headers, newurl):\n return None\n try:\n with urllib.request.build_opener(NoRedirect).open(request, timeout=45) as response:\n check(response.status == 200, \"GET did not return HTTP 200.\")\n return response.read(), {k.lower(): v for k, v in response.headers.items()}\n except urllib.error.HTTPError as exc:\n body = exc.read()\n public_headers = {k.lower(): v for k, v in exc.headers.items() if k.lower() in (\"retry-after\", \"date\", \"content-type\", \"x-request-id\") or k.lower().startswith(\"x-ratelimit\")}\n stem = \"get-error-\" + dt.datetime.now(dt.timezone.utc).strftime(\"%Y%m%dT%H%M%S%fZ\")\n write_new(ROOT / (stem + \"-body.bin\"), body)\n write_new(ROOT / (stem + \".json\"), encoded({\"method\": \"GET\", \"path\": path, \"status\": exc.code, \"response_headers\": public_headers, \"response_body\": stem + \"-body.bin\"}))\n retry = public_headers.get(\"retry-after\", \"not supplied\")\n raise ValueError(\"GET HTTP \" + str(exc.code) + \"; Retry-After: \" + retry + \". Saved response metadata/body at \" + str(ROOT / stem) + \". Snapshot stays INCOMPLETE. No automatic retry.\") from None\n\n\ndef page_meta(headers, page):\n keys = (\"page\", \"page-count\", \"item-count\", \"limit\")\n check(all(\"x-pagination-\" + k in headers for k in keys), \"Pagination headers missing: completeness is unproved, so stop.\")\n d = {k: int(headers[\"x-pagination-\" + k]) for k in keys}\n check(d[\"page\"] == page and d[\"limit\"] > 0 and d[\"item-count\"] >= 0, \"Invalid pagination metadata.\")\n if d[\"item-count\"] == 0:\n check(d[\"page-count\"] in (0, 1) and page == 1, \"Invalid empty-list pagination.\")\n else:\n check(d[\"page-count\"] == (d[\"item-count\"] + d[\"limit\"] - 1) // d[\"limit\"], \"Inconsistent page count.\")\n return d\n\n\ndef collect(kind, endpoint, destination, headers, fetcher=get):\n rawdir = destination / (kind + \"-raw\")\n rawdir.mkdir()\n all_rows, pages, stamp, first = [], [], None, None\n p, limit = 1, 100\n while True:\n path = endpoint + \"?\" + urllib.parse.urlencode({\"page\": p, \"limit\": limit})\n body, response_headers = fetcher(path, headers)\n name = \"page-%04d.json\" % p\n write_new(rawdir / name, body)\n meta = page_meta(response_headers, p)\n current = (meta[\"page-count\"], meta[\"item-count\"], meta[\"limit\"])\n stamp = current if stamp is None else stamp\n check(stamp == current, \"Dataset changed during pagination.\")\n rows = validate(kind, json.loads(body))\n count = max(0, min(meta[\"limit\"], meta[\"item-count\"] - (p - 1) * meta[\"limit\"]))\n check(len(rows) == count, \"Short page: the snapshot is incomplete.\")\n first = rows if first is None else first\n all_rows.extend(rows)\n pages.append({\"file\": name, \"sha256\": sha(body), \"pagination\": meta})\n if p >= max(1, meta[\"page-count\"]):\n break\n p, limit = p + 1, meta[\"limit\"]\n validate(kind, all_rows)\n check(len(all_rows) == stamp[1], \"Wrong total row count.\")\n body, response_headers = fetcher(endpoint + \"?\" + urllib.parse.urlencode({\"page\": 1, \"limit\": stamp[2]}), headers)\n write_new(rawdir / \"first-page-recheck.json\", body)\n final_meta = page_meta(response_headers, 1)\n check(tuple(final_meta[k] for k in (\"page-count\", \"item-count\", \"limit\")) == stamp and validate(kind, json.loads(body)) == first, \"First page or pagination changed: pause other writers and fetch again using a NEW snapshot name.\")\n data = encoded(all_rows)\n write_new(destination / (kind + \".json\"), data)\n return {\"endpoint\": endpoint, \"total\": len(all_rows), \"pages\": pages, \"first_page_recheck_sha256\": sha(body), \"sha256\": sha(data)}\n\n\ndef fetch(name):\n name = label(name)\n headers, auth_hash = auth()\n destination = ROOT / name\n destination.mkdir()\n write_new(destination / \"INCOMPLETE\", b\"Do not use this snapshot until manifest.json is complete.\\n\")\n manifest = {\"version\": 1, \"started_at\": now(), \"auth_sha256\": auth_hash, \"datasets\": {}}\n for kind, endpoint in ENDPOINTS.items():\n print(\"Fetching \" + kind + \"...\")\n manifest[\"datasets\"][kind] = collect(kind, endpoint, destination, headers)\n manifest.update({\"finished_at\": now(), \"complete\": True})\n write_new(destination / \"manifest.json\", encoded(manifest))\n (destination / \"INCOMPLETE\").unlink()\n print(\"Complete read-only snapshot: \" + str(destination) + \". Raw JSON and pagination metadata retained.\")\n\n\ndef snapshot(name):\n destination = ROOT / label(name)\n check(not (destination / \"INCOMPLETE\").exists(), \"Incomplete snapshot; no plan may use it.\")\n manifest_path = destination / \"manifest.json\"\n manifest = read_json(manifest_path)\n check(manifest.get(\"complete\") is True and manifest.get(\"version\") == 1, \"Invalid snapshot manifest.\")\n check(manifest[\"auth_sha256\"] == auth()[1], \"Credentials changed since this snapshot; use one account/token per batch.\")\n result = {\"name\": name, \"manifest_sha256\": sha(manifest_path.read_bytes())}\n for kind, endpoint in ENDPOINTS.items():\n metadata = manifest[\"datasets\"][kind]\n check(metadata[\"endpoint\"] == endpoint, \"Wrong source endpoint.\")\n body = (destination / (kind + \".json\")).read_bytes()\n check(sha(body) == metadata[\"sha256\"], \"Snapshot file was changed.\")\n rows = validate(kind, json.loads(body))\n check(len(rows) == metadata[\"total\"], \"Snapshot row count mismatch.\")\n raw_rows = []\n for page in metadata[\"pages\"]:\n raw = (destination / (kind + \"-raw\") / page[\"file\"]).read_bytes()\n check(sha(raw) == page[\"sha256\"], \"Raw page was changed.\")\n raw_rows.extend(json.loads(raw))\n check(raw_rows == rows, \"Combined snapshot differs from raw responses.\")\n raw = (destination / (kind + \"-raw\") / \"first-page-recheck.json\").read_bytes()\n check(sha(raw) == metadata[\"first_page_recheck_sha256\"], \"Raw recheck was changed.\")\n result[kind] = rows\n return result\n\n\ndef preview(name):\n s = snapshot(name)\n check(s[\"history\"], \"No movie history to repair.\")\n out = io.StringIO(newline=\"\")\n writer = csv.writer(out)\n writer.writerow([\"choose\", \"history_id\", \"movie_id\", \"title\", \"year\", \"watched_at\", \"unknown\"])\n for r in s[\"history\"]:\n m = r[\"movie\"]\n writer.writerow([\"\", \"h:\" + str(r[\"id\"]), \"m:\" + str(mid(r)), \"t:\" + str(m.get(\"title\", \"\")), m.get(\"year\"), \"at:\" + r[\"watched_at\"], \"YES\" if date(r[\"watched_at\"]) == EPOCH else \"NO\"])\n path = ROOT / (name + \"-review.csv\")\n write_new(path, (\"\\ufeff\" + out.getvalue()).encode(\"utf-8\"))\n print(\"Review \" + str(path) + \". Put exact YES only in choose for plays you personally identify as false dates. Leave all other cells unchanged. h:, m:, t:, at: keep spreadsheet cells as text.\")\n\n\ndef select(s, path):\n raw = path.read_bytes()\n choices = list(csv.DictReader(io.StringIO(raw.decode(\"utf-8-sig\"))))\n check(choices and all(c.get(\"choose\") in (\"\", \"YES\") for c in choices), \"choose must be blank or exact YES.\")\n by_id = {\"h:\" + str(r[\"id\"]): r for r in s[\"history\"]}\n unknown = {mid(r) for r in s[\"history\"] if date(r[\"watched_at\"]) == EPOCH}\n selected = []\n for c in choices:\n if c[\"choose\"] != \"YES\":\n continue\n r = by_id.get(c.get(\"history_id\"))\n check(r is not None, \"Selected history ID is missing or changed; retain h:.\")\n check(c.get(\"movie_id\") == \"m:\" + str(mid(r)), \"Movie/history mismatch; retain m:.\")\n check(c.get(\"title\") == \"t:\" + str(r[\"movie\"].get(\"title\", \"\")) and c.get(\"watched_at\") == \"at:\" + r[\"watched_at\"], \"Selected title/date cell was changed; recheck the CSV.\")\n check(mid(r) not in unknown, \"Selected movie already has an Unknown play; this workflow stops.\")\n selected.append(r)\n check(selected and len({mid(r) for r in selected}) == len(selected), \"Select exactly one false play per selected movie, and at least one movie.\")\n return selected, sha(raw)\n\n\ndef plan(name, review):\n check(not (ROOT / \"plan.json\").exists() and not (ROOT / \"add.json\").exists(), \"This working directory already has a plan; do not overwrite a repair batch.\")\n s = snapshot(name)\n selected, selection_hash = select(s, Path(review))\n for r in selected:\n print(json.dumps({\"history_id\": \"h:\" + str(r[\"id\"]), \"movie_id\": \"m:\" + str(mid(r)), \"title\": r[\"movie\"].get(\"title\"), \"old_date\": r[\"watched_at\"], \"new_date\": \"Unknown\"}, ensure_ascii=False))\n affected = watchlist(s[\"watchlist\"]) & {mid(r) for r in selected}\n accepted = False\n if affected:\n print(\"These selected movie IDs are on your Watchlist and marking watched may remove them: \" + \", \".join(\"m:\" + str(i) for i in sorted(affected)))\n check(input(\"Accept those Watchlist removals? Type YES, REMOVE FROM WATCHLIST: \") == \"YES, REMOVE FROM WATCHLIST\", \"Watchlist removal not accepted; no plan written.\")\n accepted = True\n check(input(\"Confirm only the selected false-date plays above. Type YES: \") == \"YES\", \"No plan written.\")\n review_bytes = Path(review).read_bytes()\n check(sha(review_bytes) == selection_hash, \"The selected CSV changed during confirmation; no plan written.\")\n addition = {\"movies\": [{\"ids\": {\"trakt\": mid(r)}, \"watched_at\": \"unknown\"} for r in selected]}\n p = {\"version\": 1, \"created_at\": now(), \"before\": name, \"before_manifest_sha256\": s[\"manifest_sha256\"], \"auth_sha256\": auth()[1], \"selection_sha256\": selection_hash, \"selected_history_ids\": [r[\"id\"] for r in selected], \"watchlist_accepted\": accepted, \"add_sha256\": sha(encoded(addition))}\n write_new(ROOT / \"selected-review.csv\", review_bytes)\n write_new(ROOT / \"plan.json\", encoded(p))\n write_new(ROOT / \"add.json\", encoded(addition))\n print(\"Created plan.json and add.json. No API change made. No old-play removal file exists yet. Inspect both files before the separate ADD request.\")\n\n\ndef load_plan():\n p = read_json(ROOT / \"plan.json\")\n check(p.get(\"version\") == 1 and p[\"auth_sha256\"] == auth()[1], \"Plan/authentication mismatch.\")\n s = snapshot(p[\"before\"])\n check(p[\"before_manifest_sha256\"] == s[\"manifest_sha256\"], \"The plan'"'"'s baseline was changed.\")\n by_id = {r[\"id\"]: r for r in s[\"history\"]}\n ids = p[\"selected_history_ids\"]\n check(isinstance(ids, list) and ids and all(number(i) and i in by_id for i in ids), \"Invalid selected history IDs.\")\n selected = [by_id[i] for i in ids]\n saved_selection = ROOT / \"selected-review.csv\"\n check(sha(saved_selection.read_bytes()) == p[\"selection_sha256\"], \"Saved selected CSV changed.\")\n selected_again, selection_hash = select(s, saved_selection)\n check([r[\"id\"] for r in selected_again] == ids, \"Plan history IDs differ from the exact saved CSV selection.\")\n wanted = {mid(r) for r in selected}\n check(len(wanted) == len(selected), \"More than one selected play per movie.\")\n check(not any(mid(r) in wanted and date(r[\"watched_at\"]) == EPOCH for r in s[\"history\"]), \"Baseline contains a preexisting Unknown for a selected movie.\")\n check(not watchlist(s[\"watchlist\"]) & wanted or p[\"watchlist_accepted\"] is True, \"Watchlist acceptance is absent.\")\n addition = {\"movies\": [{\"ids\": {\"trakt\": mid(r)}, \"watched_at\": \"unknown\"} for r in selected]}\n check(sha((ROOT / \"add.json\").read_bytes()) == p[\"add_sha256\"] == sha(encoded(addition)), \"ADD request differs from the bound plan.\")\n return p, s, selected, sha((ROOT / \"plan.json\").read_bytes())\n\n\ndef common(before, current, wanted, accepted):\n check(ratings(before[\"ratings\"]) == ratings(current[\"ratings\"]), \"Movie ratings or rating timestamps changed; stop.\")\n old_w, new_w = watchlist(before[\"watchlist\"]), watchlist(current[\"watchlist\"])\n allowed = old_w & wanted if accepted else set()\n check(new_w <= old_w and old_w - new_w <= allowed, \"Unexpected movie Watchlist membership change; stop.\")\n\n\ndef added_state(p, before, selected, current):\n check(current[\"name\"] != before[\"name\"], \"Use a NEW snapshot taken after the ADD request.\")\n old, new = hist(before[\"history\"]), hist(current[\"history\"])\n wanted = {mid(r) for r in selected}\n check(set(old) <= set(new) and all(new[i] == old[i] for i in old), \"An original play is missing or changed; no removal request generated.\")\n common(before, current, wanted, p[\"watchlist_accepted\"])\n added = [r for r in current[\"history\"] if r[\"id\"] not in old]\n added_m = {mid(r) for r in added}\n check(added_m <= wanted and len(added_m) == len(added) and all(date(r[\"watched_at\"]) == EPOCH for r in added), \"Unexpected new plays or duplicate Unknowns; no removal request generated.\")\n return added, wanted\n\n\ndef verify_add(name):\n p, before, selected, plan_hash = load_plan()\n current = snapshot(name)\n added, wanted = added_state(p, before, selected, current)\n added_m = {mid(r) for r in added}\n if added_m != wanted:\n report = {\"plan_sha256\": plan_hash, \"snapshot\": name, \"snapshot_manifest_sha256\": current[\"manifest_sha256\"], \"new_unknown_ids\": [r[\"id\"] for r in added], \"missing_movie_ids\": sorted(wanted - added_m)}\n write_new(ROOT / (\"add-incomplete-\" + name + \".json\"), encoded(report))\n raise ValueError(\"ADD is only partly observed (or no new play is observed). Original plays remain. Do NOT resend ADD and do NOT remove originals. Keep this report; fetch a later NEW snapshot and re-run verify-add. To abandon the attempt after requests have settled, use prepare-undo-add on a fresh snapshot. Watchlist removals are not restored by undoing new plays.\")\n removal = {\"ids\": [r[\"id\"] for r in selected]}\n certificate = {\"plan_sha256\": plan_hash, \"after_add\": name, \"after_add_manifest_sha256\": current[\"manifest_sha256\"], \"unknown_plays\": added, \"remove_sha256\": sha(encoded(removal))}\n certificate_path = ROOT / \"add-verified.json\"\n if certificate_path.exists():\n saved = read_json(certificate_path)\n check(all(saved.get(k) == v for k, v in certificate.items()), \"Existing ADD certificate belongs to different evidence; do not overwrite it.\")\n else:\n check(not (ROOT / \"remove.json\").exists(), \"An unbound REMOVE file already exists; stop.\")\n certificate[\"verified_at\"] = now()\n write_new(certificate_path, encoded(certificate))\n write_same(ROOT / \"remove.json\", encoded(removal))\n print(\"ADD verified: every original play remains unchanged to its movie/date-minute/action, ratings are unchanged, and each target has exactly one new Unknown. Created remove.json containing only selected ORIGINAL history IDs. Inspect it before the separate REMOVE request.\")\n\n\ndef verify_final(name):\n p, before, selected, plan_hash = load_plan()\n certificate = read_json(ROOT / \"add-verified.json\")\n check(certificate[\"plan_sha256\"] == plan_hash, \"ADD verification is bound to a different plan.\")\n after_add = snapshot(certificate[\"after_add\"])\n check(certificate[\"after_add_manifest_sha256\"] == after_add[\"manifest_sha256\"], \"Verified ADD snapshot changed.\")\n actual_added, wanted = added_state(p, before, selected, after_add)\n check({mid(r) for r in actual_added} == wanted and certificate[\"unknown_plays\"] == actual_added, \"ADD certificate does not match the bound raw snapshot.\")\n removal = {\"ids\": [r[\"id\"] for r in selected]}\n check(sha((ROOT / \"remove.json\").read_bytes()) == certificate[\"remove_sha256\"] == sha(encoded(removal)), \"REMOVE request changed.\")\n current = snapshot(name)\n check(name not in (before[\"name\"], after_add[\"name\"]), \"Use a NEW snapshot taken after the REMOVE request.\")\n removed = {r[\"id\"] for r in selected}\n unknown = certificate[\"unknown_plays\"]\n validate(\"history\", unknown)\n expected = {i: sig for i, sig in hist(before[\"history\"]).items() if i not in removed}\n expected.update(hist(unknown))\n actual = hist(current[\"history\"])\n allowed_originals = {r[\"id\"]: signature(r) for r in selected}\n check(set(expected) <= set(actual) and all(actual[i] == expected[i] for i in expected), \"A retained or newly verified play is missing/changed; stop.\")\n remaining = set(actual) - set(expected)\n check(remaining <= removed and all(actual[i] == allowed_originals[i] for i in remaining), \"Unexpected final history change; stop.\")\n check(ratings(before[\"ratings\"]) == ratings(current[\"ratings\"]), \"Movie ratings or rating timestamps changed; stop.\")\n check(watchlist(after_add[\"watchlist\"]) == watchlist(current[\"watchlist\"]), \"Movie Watchlist membership changed during removal; stop.\")\n if remaining:\n path = ROOT / (\"remaining-remove-\" + name + \".json\")\n write_new(path, encoded({\"ids\": sorted(remaining)}))\n raise ValueError(\"REMOVE is incomplete. Fresh snapshot confirms only these selected original IDs remain; \" + str(path) + \" contains ONLY those IDs. Inspect it before any explicit retry of REMOVE; never resend ADD. Then fetch and verify a NEW final snapshot.\")\n report = {\"plan_sha256\": plan_hash, \"final_snapshot\": name, \"final_manifest_sha256\": current[\"manifest_sha256\"], \"verified_at\": now(), \"condition\": \"H0 minus S plus verified U; movie ratings unchanged; Watchlist membership unchanged since verified ADD\"}\n write_new(ROOT / (\"final-verified-\" + name + \".json\"), encoded(report))\n print(\"FINAL VERIFIED: original history minus only selected false-date plays plus their verified Unknown replacements. Existing real rewatches retained; movie ratings unchanged. Watchlist acceptance, if any, still applies.\")\n\n\ndef prepare_undo(name):\n p, before, selected, plan_hash = load_plan()\n current = snapshot(name)\n added, wanted = added_state(p, before, selected, current)\n check(added, \"No new Unknown plays observed to undo. Do not issue an empty removal request.\")\n payload = {\"ids\": [r[\"id\"] for r in added]}\n path = ROOT / (\"undo-add-\" + name + \".json\")\n write_new(path, encoded(payload))\n report = {\"plan_sha256\": plan_hash, \"snapshot\": name, \"snapshot_manifest_sha256\": current[\"manifest_sha256\"], \"payload_sha256\": sha(encoded(payload)), \"new_unknown_ids\": payload[\"ids\"]}\n write_new(ROOT / (\"undo-plan-\" + name + \".json\"), encoded(report))\n print(\"Optional abandonment request: \" + str(path) + \" removes ONLY new Unknown plays verified against the baseline. All original plays still exist. Inspect it, then use a separate explicit REMOVE request. This does not restore removed Watchlist membership. Afterward fetch a NEW snapshot and run verify-undo.\")\n\n\ndef verify_undo(name):\n p, before, selected, plan_hash = load_plan()\n current = snapshot(name)\n check(name != before[\"name\"], \"Use a NEW snapshot after the undo request.\")\n check(hist(before[\"history\"]) == hist(current[\"history\"]), \"History is not restored to the original IDs/movie/date-minute/action; stop.\")\n common(before, current, {mid(r) for r in selected}, p[\"watchlist_accepted\"])\n report = {\"plan_sha256\": plan_hash, \"snapshot\": name, \"snapshot_manifest_sha256\": current[\"manifest_sha256\"], \"verified_at\": now(), \"condition\": \"Original movie history and ratings restored; accepted Watchlist removals may remain\"}\n write_new(ROOT / (\"undo-verified-\" + name + \".json\"), encoded(report))\n print(\"UNDO VERIFIED: original movie history and ratings are present. Accepted Watchlist removals may remain. Abandon this batch; do not run its old add.json or remove.json. Use a fresh working directory for any later attempt.\")\n\n\ndef main():\n os.umask(0o077)\n parser = argparse.ArgumentParser(description=__doc__)\n sub = parser.add_subparsers(dest=\"command\", required=True)\n sub.add_parser(\"init\").add_argument(\"headers_file\")\n for command in (\"fetch\", \"preview\", \"verify-add\", \"verify-final\", \"prepare-undo-add\", \"verify-undo\"):\n sub.add_parser(command).add_argument(\"snapshot\")\n p = sub.add_parser(\"plan\")\n p.add_argument(\"snapshot\")\n p.add_argument(\"review_csv\")\n args = parser.parse_args()\n try:\n if args.command == \"init\":\n init(args.headers_file)\n elif args.command == \"fetch\":\n fetch(args.snapshot)\n elif args.command == \"preview\":\n preview(args.snapshot)\n elif args.command == \"plan\":\n plan(args.snapshot, args.review_csv)\n elif args.command == \"verify-add\":\n verify_add(args.snapshot)\n elif args.command == \"verify-final\":\n verify_final(args.snapshot)\n elif args.command == \"prepare-undo-add\":\n prepare_undo(args.snapshot)\n elif args.command == \"verify-undo\":\n verify_undo(args.snapshot)\n except (ValueError, KeyError, TypeError, OSError, csv.Error, urllib.error.HTTPError, urllib.error.URLError) as exc:\n print(\"STOP: \" + str(exc) + \"\\nNo mutation request was sent by this helper. Preserve existing files; do not overwrite snapshots or blindly repeat a POST.\", file=sys.stderr)\n raise SystemExit(2)\n\n\nif __name__ == \"__main__\":\n main()\n"; p.open("x",encoding="utf-8",newline="").write(source); hashlib.sha256(p.read_bytes()).hexdigest()=='"'"'21c8f1a918bd1b8d818476f57b2f7cab9ccfa56504da40fc1c586325d8aa2ded'"'"' or sys.exit("STOP: source SHA mismatch"); print("Complete source written locally. SHA-256: 21c8f1a918bd1b8d818476f57b2f7cab9ccfa56504da40fc1c586325d8aa2ded. Open and inspect trakt_repair.py before running it. No API request made.")'
源码写出命令会显示生成文件的 SHA-256。本版本已审核源码的 SHA-256 为 21c8f1a918bd1b8d818476f57b2f7cab9ccfa56504da40fc1c586325d8aa2ded。如果显示值不同,应停止,并在新的空工作目录中重新复制完整命令。