기술 · 실용 가이드
Trakt로 가져온 영화 기록의 잘못된 시청 날짜 바로잡기
영화의 시청 완료 상태를 유지하면서 선택한 잘못된 날짜를 Unknown(날짜 미상)으로 바꿉니다. 먼저 해당 가져오기 작업을 정확히 식별해 실행 취소할 수 있는지 확인하세요. 그렇지 않다면 개별 시청 기록을 검토하고, 기존 기록을 삭제하기 전에 대체 기록을 검증하세요.
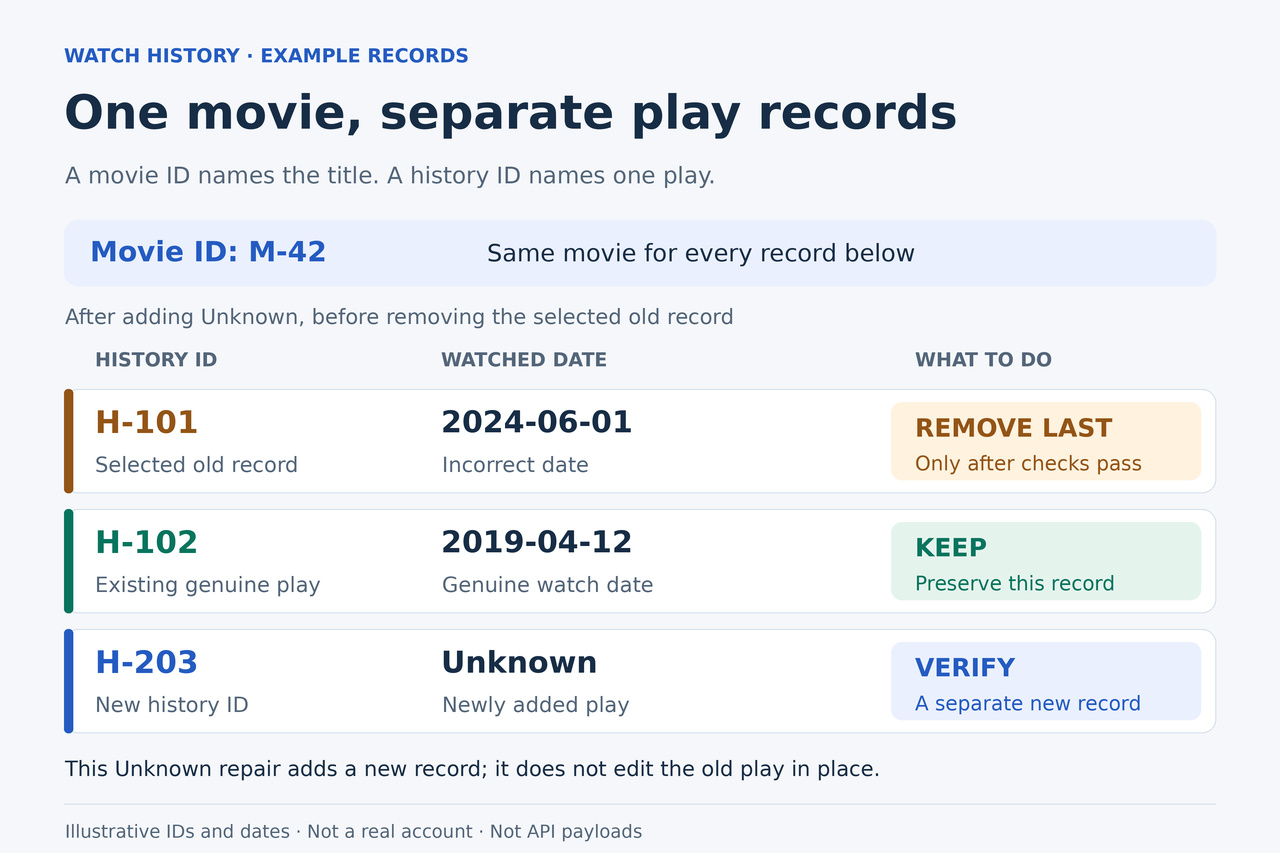
예전에 IMDb나 Letterboxd에서 가져온 기록 때문에 모든 영화를 하루에 본 것처럼 표시된다면, Trakt의 Unknown(날짜 미상)을 사용해 시청 날짜를 지어내지 않으면서 해당 영화를 봤다는 사실을 유지할 수 있습니다. Unknown 시청 기록은 총 시청 횟수에는 포함되지만 날짜 기반 통계에서는 제외됩니다. Unknown을 추가하는 것만으로 기존의 잘못된 날짜가 붙은 시청 기록이 삭제되지는 않습니다.
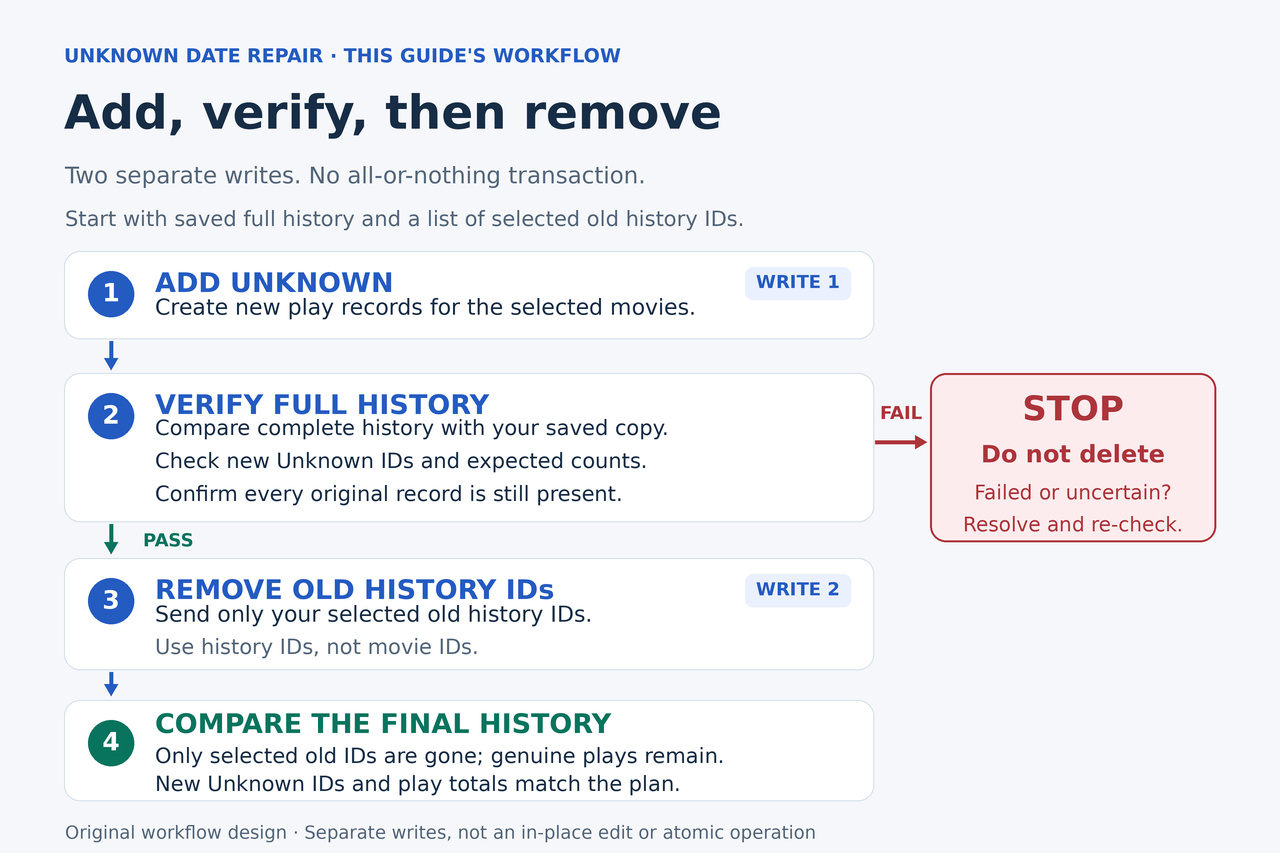
먼저 원치 않는 가져오기 작업을 정확히 식별해 실행 취소할 수 있는지 확인하세요. 일부 기록만 수정하려는 경우를 위해 이 가이드는 완전한 로컬 Python 보조 프로그램을 제공합니다. 잘못된 시청 기록을 선택하고, 이를 대체할 Unknown 기록을 추가한 뒤 결과를 검증하고, 그다음에 선택한 원래 history ID만 삭제합니다. 보조 프로그램은 데이터를 읽고 파일을 준비합니다. 두 번의 계정 변경은 별도 명령으로 분리돼 있으며, 사용자가 직접 내용을 확인하고 실행합니다.
어떤 날짜가 실제로 잘못됐는지 판단하세요
새로 만든 Trakt 백업과 함께 원본 가져오기 파일을 보관하세요. 날짜가 한곳에 몰린 기록은 검토 후보를 찾는 단서가 될 수 있지만, 그날의 모든 시청 기록이 잘못됐다는 증거는 아닙니다. 영화, 원본 기록, 자신의 기억을 함께 확인하세요. 실제로 같은 날 본 기록은 수정 대상에서 제외하세요.
Letterboxd는 언젠가 영화를 봤다고 표시하는 것과 Diary(다이어리)에 특정 시청을 기록하는 것을 구분합니다. 원본 파일의 Date 열이 반드시 시청 날짜를 뜻하는 것은 아닙니다. 날짜를 지정해 수정할 때 쓸 수 있도록 신뢰할 수 있는 Diary 날짜는 보존하세요. 이번 배치는 실제 시청 날짜를 모르는 기록만 대상으로 합니다.
하나의 계획에서 영화 한 편당 잘못된 시청 기록을 최대 하나만 선택하세요. 날짜가 정확한 재시청 기록은 남겨두세요. 선택한 영화에 이미 Unknown 시청 기록이 있다면 중단하고 각 기록이 무엇을 나타내는지 판단하세요. 이 보조 프로그램은 그런 기록을 병합하지 않으며, 날짜를 모르는 여러 번의 재시청을 별도로 표현할 수 있다고 보장하지도 않습니다.
정확한 가져오기 작업을 실행 취소할 수 있는지 확인하세요
Trakt 문서에 따르면 GET /users/syncs/import로 가져오기 동기화 작업 목록을 조회하고, GET /users/syncs/ID로 특정 작업을 살펴보며, DELETE /users/syncs/ID로 이를 실행 취소할 수 있습니다. sync ID는 가져오기 작업을 식별하며, movie ID나 history ID와는 다릅니다. 오래된 가져오기 작업을 찾을 때는 반환되는 모든 페이지를 확인하세요.
기록을 통해 원치 않는 가져오기 작업을 확실히 식별할 수 있고, 해당 가져오기 전체를 되돌리려는 경우에만 이 대안을 사용하세요. 실행 취소는 가져온 시청 기록, 평점, 일시 정지 항목, Watchlist, 컬렉션을 되돌릴 수 있습니다. 날짜가 같거나 개수가 비슷하다는 이유만으로 같은 작업이라고 판단할 수는 없습니다. 제공된 기록으로 해당 배치를 식별할 수 없다면 건드리지 말고, 선택한 기록만 수정하는 절차를 사용하세요.
과거의 모든 파일 가져오기에 식별 가능한 sync 기록이 있거나 현재 화면에 실행 취소 버튼이 있다고 가정하지 마세요. 확인된 배치를 실행 취소했다면 결과를 다시 읽어 확인하고, 원본 소스에서 수정할 입력 데이터를 준비한 뒤, 작품 매칭과 선택한 데이터 유형을 미리 확인하고 다시 가져온 결과를 검증하세요. 이후에 일부 기록을 선택해 수정할 계획을 세운다면, 실행 취소 후 새로 읽어온 기준 데이터에서 시작하세요.
접근 권한, 백업, 비공개 작업 폴더를 준비하세요
Bash와 Python 3.10 이상, curl 7.76.0 이상을 사용하세요. 아래에 연결된 최신 공식 지침에 따라 사용이 허용된 본인의 Trakt 애플리케이션으로 접근 권한을 얻고, 자신의 계정에 대한 권한을 부여하세요. 앱을 등록하려면 인증된 GitHub 연결과 사용 가능한 애플리케이션 등록 슬롯이 필요하며, 실제 계정 제한과 승인 조건이 적용됩니다. 이 글은 무료 사용량이 고정돼 있거나 누구나 VIP가 필요하다고 가정하지 않습니다.
보조 프로그램을 사용하기 전에 Trakt의 필수 헤더 및 OAuth 문서에 따라 로컬 요청 헤더 파일을 준비하세요. 이 파일에는 Authorization, trakt-api-key, trakt-api-version, Content-Type, User-Agent 필드가 한 줄에 하나씩 있어야 하며, API 버전은 2, 콘텐츠 유형은 JSON을 사용해야 합니다. 본인에게 승인된 값을 사용하고, 파일은 비공개로 보관하며, 내용을 이 웹사이트에 붙여 넣지 마세요. 보조 프로그램은 이미 준비된 파일을 가져올 뿐, 앱을 등록하거나 접근 권한을 만들어주지 않습니다.
현재 OAuth 호스트는 auth.trakt.tv이며, 아래 데이터 명령은 api.trakt.tv를 사용합니다. 기기 인증 방식을 사용한다면 응답에 나온 폴링 간격과 만료 시간을 따르세요. 한 배치에서는 동일한 유효 인증 정보 파일을 계속 사용하세요. 저장된 스냅샷이 그 파일에 연결됩니다. 도중에 접근 권한이 만료되거나 파일이 바뀌면 중단하고 배치 파일을 보존하세요. 이 보조 프로그램은 일부만 완료된 배치를 새 인증 정보로 옮기는 기능을 제공하지 않습니다.
데이터를 변경하기 전에 계정 데이터를 내보내세요. 현재 JSON ZIP에서 개별 시청 기록은 watched-history.json 또는 번호가 붙은 watched-history-N.json 파일에 들어 있습니다. watched-movies.json은 집계 파일입니다. 내보내기 결과를 살펴보고, _errors.json이 있다면 함께 확인하세요. ZIP을 내려받았더라도 내용이 일부만 포함됐을 수 있습니다. 필요한 정보에 영향을 주는 오류를 해결한 뒤에야 사용 가능한 백업으로 취급하세요.
자동 시청 기록 도구인 스크로블러와 자동 가져오기를 일시 중지하고, 검증이 끝날 때까지 다른 시청 기록·평점·Watchlist 수정도 피하세요. 이번 배치를 위한 새로운 빈 로컬 폴더를 만들고 그 안에서 Bash를 여세요. 공식 내보내기 파일은 별도로 보관하세요. 페이지별 조회는 한 시점의 계정 상태를 원자적으로 포착하는 스냅샷이 아닙니다. 다른 쓰기 작업을 중지하고 모든 페이지를 검사하면 오류를 줄일 수는 있지만, API를 트랜잭션으로 만들 수는 없습니다.
보조 프로그램을 설치한 뒤 완전한 기준 스냅샷을 읽어오세요
글 끝의 「로컬 보조 프로그램 전체 코드」에는 소스 파일을 만드는 완전한 명령 하나가 있습니다. 빈 작업 폴더에서 해당 명령 전체를 Bash에 복사하세요. 이 명령은 로컬에 trakt_repair.py를 만들며, API를 요청하지 않고, 기존 파일을 덮어쓰지도 않습니다. 실행하기 전에 생성된 읽을 수 있는 Python 파일을 열어보세요. 코드의 주석, 프롬프트, 명령은 모든 언어판에서 영어로 유지됩니다.
공식 지침에 따라 준비한 비공개 헤더 파일로 보조 프로그램을 초기화하세요. 아래 명령의 예시 파일 경로를 실제 로컬 경로로 바꾸고, 공백이 있는 경로는 따옴표로 감싸세요. 이후 모든 명령도 같은 작업 폴더에서 실행하세요. 가져온 인증 정보와 작업 데이터는 trakt-repair 아래의 비공개 파일로 저장됩니다.
python3 trakt_repair.py init trakt-headers.txt
기준 스냅샷을 읽어오세요. 이 명령은 영화 시청 기록, 영화 평점, 영화 Watchlist에 대해 인증된 GET 요청만 보냅니다. 원본 응답 바이트, 페이지 조회 메타데이터, 완전하게 합친 JSON 파일을 보존합니다.
python3 trakt_repair.py fetch before
완전한 스냅샷을 얻었다고 보고할 때만 진행하세요. 수집기는 응답에 나온 페이지 수, 실제 적용된 한도, 항목 수를 사용한 뒤 첫 페이지를 다시 확인합니다. 페이지 조회 정보가 없거나, 페이지의 항목 수가 기대보다 적거나, ID가 중복되거나, 영화 데이터 구조가 예상과 다르거나, 변화가 관찰되면 해당 스냅샷은 사용할 수 없는 상태로 남습니다. 강제로 통과시키려고 INCOMPLETE를 삭제하지 마세요. 읽기 오류를 해결했다면 새로운 스냅샷 이름으로 조회하고, 이후 preview와 plan 명령에도 그 이름을 사용하세요.
완전한 기준 스냅샷에서 검토용 CSV를 만드세요. Python은 원래의 큰 정수 ID를 그대로 유지합니다. 검토 파일은 h:, m:, t:, at: 접두사를 사용해 식별자, 제목, 타임스탬프를 스프레드시트에서 텍스트로 유지합니다.
python3 trakt_repair.py preview before
잘못된 시청 기록을 선택하고 계획을 확인하세요
trakt-repair/before-review.csv를 여세요. 날짜가 잘못됐다고 직접 확인한 시청 기록만 choose 열에 정확히 YES로 표시한 다음, UTF-8 CSV로 저장하세요. 다른 모든 셀과 접두사는 변경하지 마세요. 타임스탬프는 API의 타임스탬프이며, Trakt 화면의 Today 표시는 다른 표시 시간대를 반영할 수 있습니다. 보조 프로그램은 계획을 만들 때 선택 사항이 담긴 CSV 사본도 별도로 저장합니다.
python3 trakt_repair.py plan before trakt-repair/before-review.csv
계획 단계에서는 선택한 각 history ID를 원본 기준 스냅샷과 대조하고, 영화·제목·원래 타임스탬프를 검증합니다. 같은 영화를 중복 선택했거나 선택한 영화에 이미 Unknown이 있다면 거부합니다. 제안하는 대체 기록을 출력하고, 정확히 YES를 입력해야 계획을 저장합니다. Trakt는 타임스탬프를 분 단위로 정규화하고 작품과 시각의 조합으로 중복을 제거한다고 발표했습니다. 초를 바꾸는 것으로 날짜를 모르는 재시청 기록을 별도로 보존할 수는 없습니다.
선택한 영화가 기본 Watchlist에 있으면 계획에 해당 movie ID가 표시되며, 목록에서 제거되는 것을 수락하는지 별도로 묻습니다. Trakt는 작품을 시청 완료로 표시할 때 이 목록에서 제거할 수 있고, 확인한 자료에는 Unknown이 예외라는 근거가 없습니다. 이 결과를 받아들일 때만 YES, REMOVE FROM WATCHLIST를 입력하세요. 그렇지 않다면 중단하고 해당 작품을 제외한 뒤 다시 검토하세요. 검사 대상은 Watchlist에 작품이 포함돼 있는지 여부이며, 메모·순위·처음 추가한 날짜의 보존 여부는 아닙니다.
텍스트 편집기에서 trakt-repair/plan.json과 trakt-repair/add.json을 확인하세요. 추가 요청은 movie ID를 사용하고 watched_at을 리터럴 문자열 unknown으로 지정합니다. null로 바꾸거나 값을 생략하거나 임의의 과거 날짜를 사용하지 마세요. 이 단계에서는 삭제 요청이 아직 없습니다. 잘못된 것으로 확인한 시청 기록 하나부터 시작하세요. 최종 검사를 통과하면, 더 큰 배치를 위해 새로운 빈 상위 작업 폴더를 만들고 기준 스냅샷을 새로 읽어오세요. 기존 계획을 덮어쓰지 않는 것은 의도된 동작입니다.
Unknown을 추가하고 대체 기록을 검증하세요
다음 명령이 첫 번째 계정 변경입니다. add.json을 확인한 뒤 한 번만 실행하세요. 응답 본문과 헤더를 보관하세요. 각 쓰기 명령은 아직 사용하지 않은 응답 파일명을 요구하고, 숨겨진 curl 설정을 비활성화하며, 자동 재시도나 리디렉션 옵션을 사용하지 않습니다. 응답 파일이 이미 있다는 이유로 거부되면 저장된 상태를 확인해야 합니다. 파일을 지우고 쓰기를 반복해서는 안 됩니다.
test ! -e trakt-repair/add-response.json && test ! -e trakt-repair/add-response-headers.txt && curl -q --fail-with-body --silent --show-error --request POST --header @trakt-repair/auth.headers --data-binary @trakt-repair/add.json --dump-header trakt-repair/add-response-headers.txt --output trakt-repair/add-response.json --write-out 'HTTP %{http_code}\n' https://api.trakt.tv/sync/history
요청에 대한 응답이 돌아오면 오류나 불확실한 응답이었더라도 완전한 새 스냅샷을 읽어오고 중간 검사를 실행하세요. 추가 개수나 HTTP 성공 결과만으로는 현재 어떤 시청 기록 ID가 존재하는지 확인할 수 없습니다.
python3 trakt_repair.py fetch after-add
python3 trakt_repair.py verify-add after-add
검사는 선택한 영화마다 새로운 Unknown history ID가 정확히 하나 있어야 통과합니다. 동시에 원래의 모든 영화 시청 기록은 같은 영화, 분 단위로 정규화한 타임스탬프, action 값을 유지한 채 남아 있어야 합니다. 영화 평점과 평점을 매긴 타임스탬프도 일치해야 합니다. 계획에서 수락한 Watchlist 제거만 허용되며, 항목이 추가되거나 무관한 항목이 사라지면 중단됩니다.
다시 읽어 검증할 때 Unknown은 정확한 UTC 시점 1970-01-01T00:00:00Z입니다. 같은 시점을 나타내는 .000Z 표기도 동일한 시점으로 취급합니다. 보조 프로그램은 날짜 전체나 연도만으로 판단하지 않고 파싱한 시점을 비교합니다. 요청에서는 계속 리터럴 문자열 unknown을 사용합니다. 검증된 새 ID는 원래 선택한 ID와 별도로 저장됩니다.
중간 검사를 통과해야만 trakt-repair/add-verified.json과 trakt-repair/remove.json이 생성됩니다. 뒤의 파일을 확인하세요. 최상위 ids 배열에는 선택한 원래 history ID만 있어야 합니다. movies 배열은 삭제 범위가 더 넓으므로 이를 대신 사용하면 안 됩니다. 새 Unknown ID는 이 요청에 포함되면 안 됩니다.
일시적으로 선택한 영화마다 시청 기록이 하나씩 늘어납니다. 이 절차는 기존 기록을 삭제하기 전에 대체 기록을 검증하므로, 시청 기록이 의도적으로 0개가 되는 구간을 피합니다. 그래도 이는 계정에 부수적인 영향을 줄 수 있는 두 번의 별도 API 쓰기이며, 기존 기록의 날짜를 제자리에서 수정하는 작업은 아닙니다.
기존 ID만 삭제하고 완료 여부를 검증하세요
중간 검사를 통과하고 remove.json을 확인한 뒤에만 두 번째 계정 변경 명령을 실행하세요. deleted와 not_found 정보를 포함해 응답을 보존하세요.
test ! -e trakt-repair/remove-response.json && test ! -e trakt-repair/remove-response-headers.txt && curl -q --fail-with-body --silent --show-error --request POST --header @trakt-repair/auth.headers --data-binary @trakt-repair/remove.json --dump-header trakt-repair/remove-response-headers.txt --output trakt-repair/remove-response.json --write-out 'HTTP %{http_code}\n' https://api.trakt.tv/sync/history/remove
새로운 완전한 스냅샷을 읽어오고 최종 결과를 확인하세요.
python3 trakt_repair.py fetch final
python3 trakt_repair.py verify-final final
성공한 결과는 원래 영화 시청 기록에서 선택한 기존 ID를 빼고, 앞서 검증한 특정 새 Unknown ID를 더한 상태입니다. 선택하지 않은 모든 원본 시청 기록과 각 대체 기록은 예상한 영화, 정규화된 타임스탬프, action 값을 계속 유지해야 합니다. 영화 평점은 바뀌지 않아야 하며, 영화 Watchlist에 포함된 작품은 추가 직후에 얻은 스냅샷과 일치해야 합니다. 총개수가 같다는 이유만으로 통과하지는 않습니다.
이 조건이 충족되면 보조 프로그램이 final-verified-final.json을 만듭니다. 선택한 시청 기록마다 하나씩 대체하므로 영화 시청 횟수는 기준 총개수로 돌아가고, 실제 날짜가 있는 재시청 기록은 남습니다. Trakt에서 수정한 영화 몇 편을 직접 열어 별도로 화면도 확인하세요. 시청 완료 상태가 유지되고 Unknown 시청 기록이 있어야 하며, 선택했던 잘못된 날짜는 더 이상 나타나지 않아야 합니다. Unknown은 날짜 기반 그래프에서 제외되도록 설계돼 있습니다.
원본 소스, 공식 내보내기 파일, 원본 스냅샷, 선택 사항이 담긴 CSV, 계획, 요청, 응답, 검증 파일을 비공개로 보관하세요. 대체 기록은 새 history ID를 가지며, 이 과정은 삭제된 시청 기록의 원래 스크로블 또는 체크인 식별 정보를 보존하지 않습니다. 최종 결과를 확인하고 받아들인 뒤에만 일시 중지한 가져오기를 재개하세요.
읽기나 추가가 중단되면 저장된 단계의 상태를 보존하세요
읽기가 실패했다면 완전한 기준 데이터나 결과가 확보됐다고 볼 수 없습니다. HTTP 오류가 발생하면 보조 프로그램은 응답 상태, 관련 응답 헤더, 본문을 타임스탬프가 붙은 get-error 파일에 저장하며, 요청 인증 정보는 그곳에 저장하지 않습니다. 스냅샷은 INCOMPLETE 상태로 남습니다. 보고된 문제를 해결한 뒤 새로운 스냅샷 이름을 선택하세요. 실패 근거를 덮어쓰지 마세요.
추가 결과가 일부만 관찰되면 verify-add가 새 Unknown ID와 이번 조회에서 아직 확인되지 않은 영화를 식별하는 add-incomplete 보고서를 만듭니다. remove.json은 생성하지 않습니다. 추가 요청 전체를 다시 보내거나 원래 기록을 삭제하지 마세요. 진행 중이던 요청의 처리가 끝나면 새로운 이름으로 이후 시점의 스냅샷을 가져오고, 그 이름으로 verify-add를 실행하세요. 그때 예상한 전체 결과가 나타나면 검증된 단계에서 계속 진행하세요.
이 보조 프로그램은 빠진 추가 항목에 대한 자동 요청을 생성하지 않습니다. 결과가 계속 부분적으로만 나타나면 보고서를 보관하고 이번 수정 시도를 중단하거나, 새로 확인한 뒤 아래의 추가 취소 분기를 사용하세요. 예상하지 못한 새 시청 기록, 사라진 원본, 변경된 평점, 수락하지 않은 Watchlist 변경은 원인을 조사해야 합니다. 강제로 통과시키려고 매니페스트를 고치거나 검사를 제거하지 마세요.
Trakt 문서에는 인증된 쓰기는 초당 1회, 인증된 GET 요청은 5분당 500회로 제한된다고 나와 있습니다. 429 응답의 Retry-After를 따르세요. 다른 애플리케이션과 계정 한도를 공유할 수 있습니다. 인증, 애플리케이션 승인, 계정 한도, 유효하지 않은 데이터는 서로 다른 오류입니다. 토큰을 바꾼다고 모든 403, 420, 422, 426 응답이 해결되는 것은 아니며, 이 보조 프로그램은 진행 중인 배치를 기존 인증 정보 파일에 연결합니다.
삭제가 일부만 됐다면 남은 선택 ID만 재시도하세요
삭제 응답이 불확실하면 먼저 새 스냅샷을 가져오고 verify-final을 실행하세요. 유지해야 할 기록이 모두 올바르고 선택한 원래 ID 중 일부만 남았다면, 보조 프로그램이 그 ID만 담은 remaining-remove 파일을 만듭니다. 완료를 보고하지 않고 중단합니다. 개수 불일치를 해결하려고 한 영화의 모든 시청 기록을 삭제하는 일은 하지 않습니다.
다음 예시는 verify-final final이 trakt-repair/remaining-remove-final.json을 만든 경우에만 적용됩니다. 사용 전에 바로 그 파일을 확인하세요. 스냅샷 이름이 다르다면 보조 프로그램이 실제로 보고한 remaining-remove 파일명과 새로운 응답 파일명을 사용하세요.
test ! -e trakt-repair/remove-retry-response.json && test ! -e trakt-repair/remove-retry-response-headers.txt && curl -q --fail-with-body --silent --show-error --request POST --header @trakt-repair/auth.headers --data-binary @trakt-repair/remaining-remove-final.json --dump-header trakt-repair/remove-retry-response-headers.txt --output trakt-repair/remove-retry-response.json --write-out 'HTTP %{http_code}\n' https://api.trakt.tv/sync/history/remove
그런 다음 새 스냅샷을 다시 얻고 동일한 최종 조건을 검사하세요. 삭제 복구의 일부로 추가를 반복하면 안 됩니다.
python3 trakt_repair.py fetch final-2
python3 trakt_repair.py verify-final final-2
선택 사항: 원래 기록을 삭제하기 전에 추가한 Unknown을 취소하세요
모든 원래 시청 기록이 아직 존재하는 상태에서 추가를 취소하려는 경우에만 이 분기를 사용하세요. 진행 중인 요청이 마무리되게 하고 다른 쓰기 작업은 계속 중지해 두세요. 보조 프로그램은 원래 시청 기록과 평점이 온전하며, 새 시청 기록은 선택한 영화당 최대 하나의 Unknown뿐이라는 사실을 확인해야 합니다. 수락했던 Watchlist 제거는 그대로 남을 수 있습니다. 이는 계정 전체를 되돌리는 작업이 아닙니다.
python3 trakt_repair.py fetch undo-check
python3 trakt_repair.py prepare-undo-add undo-check
보조 프로그램이 undo-add-undo-check.json을 생성한 경우에만 파일을 열어, 원래 ID가 아니라 새로 추가된 Unknown history ID가 들어 있는지 확인하세요. 다음 명령은 바로 그 새 시청 기록을 명시적으로 삭제합니다. 보조 프로그램이 거부하면 더 넓은 범위의 요청을 직접 만들지 말고, 파일을 보존한 채 원인을 조사하세요.
test ! -e trakt-repair/undo-add-response.json && test ! -e trakt-repair/undo-add-response-headers.txt && curl -q --fail-with-body --silent --show-error --request POST --header @trakt-repair/auth.headers --data-binary @trakt-repair/undo-add-undo-check.json --dump-header trakt-repair/undo-add-response-headers.txt --output trakt-repair/undo-add-response.json --write-out 'HTTP %{http_code}\n' https://api.trakt.tv/sync/history/remove
다시 읽어 원래 영화 시청 기록과 평점이 있는지 검증하세요. 앞서 수락했던 Watchlist 항목 손실은 별도로 검토하세요.
python3 trakt_repair.py fetch undone
python3 trakt_repair.py verify-undo undone
추가 취소를 마쳤다면 이 배치는 더 이상 사용하지 마세요. 나중에 기존 add.json이나 remove.json을 실행하면 안 됩니다. 새 시도에는 새로운 빈 작업 폴더와 새 기준 데이터가 필요합니다. 스냅샷으로 정확히 무슨 일이 있었는지 확인할 수 없다면, 삭제할 ID를 추측하지 말고 남아 있는 기록을 보존한 채 민감한 내용을 가린 계획을 사용해 도움을 요청하세요.
로컬 보조 프로그램 전체 코드
다음 문단의 전체 명령을 하나의 Bash 명령으로 복사하세요. 이 명령은 읽을 수 있는 소스 파일만 작성하며, 보조 프로그램을 실행하거나 Trakt에 접속하지 않습니다. 이후 trakt_repair.py를 열어본 뒤 「보조 프로그램을 설치한 뒤 완전한 기준 스냅샷을 읽어오세요」로 돌아가세요. 직선 따옴표와 백슬래시를 그대로 유지하고, 이 명령을 번역하지 마세요.
python3 -c 'from pathlib import Path; import hashlib,sys; p=Path("trakt_repair.py"); source="#!/usr/bin/env python3\n\"\"\"Movie-history repair helper: local files and authenticated GET requests only.\n\nThis program NEVER sends POST, DELETE or PUT requests. Inspect its generated\nJSON, then use separate explicit curl commands. Python 3.10+; Bash examples.\nAPI response contracts were checked against the Trakt authors'"'"' published code.\nNo live account or device was used to test this helper. Pause other imports,\nscrobblers and history edits until the final check. Pagination is not atomic.\n\"\"\"\nimport argparse\nimport csv\nimport datetime as dt\nimport hashlib\nimport io\nimport json\nimport os\nfrom pathlib import Path\nimport re\nimport sys\nimport time\nimport urllib.error\nimport urllib.parse\nimport urllib.request\n\nROOT = Path(\"trakt-repair\")\nAPI = \"https://api.trakt.tv\"\nENDPOINTS = {\"history\": \"/users/me/history/movies\", \"ratings\": \"/users/me/ratings/movies\", \"watchlist\": \"/users/me/watchlist/movies/rank\"}\nEPOCH = dt.datetime(1970, 1, 1, tzinfo=dt.timezone.utc)\nLAST_GET = 0.0\n\n\ndef check(ok, why):\n if not ok:\n raise ValueError(why)\n\n\ndef sha(data):\n return hashlib.sha256(data).hexdigest()\n\n\ndef encoded(value):\n return (json.dumps(value, ensure_ascii=False, indent=2) + \"\\n\").encode(\"utf-8\")\n\n\ndef read_json(path):\n return json.loads(path.read_bytes())\n\n\ndef write_new(path, data):\n with path.open(\"xb\") as f:\n f.write(data)\n\n\ndef write_same(path, data):\n if path.exists():\n check(path.read_bytes() == data, \"Existing output differs; it will not be overwritten: \" + str(path))\n else:\n write_new(path, data)\n\n\ndef now():\n return dt.datetime.now(dt.timezone.utc).isoformat()\n\n\ndef number(v):\n return type(v) is int and 0 < v <= 9223372036854775807\n\n\ndef date(v):\n check(isinstance(v, str), \"Missing or non-string timestamp; null is not Unknown.\")\n d = dt.datetime.fromisoformat(v.replace(\"Z\", \"+00:00\"))\n check(d.tzinfo is not None, \"Timestamp has no timezone.\")\n return d.astimezone(dt.timezone.utc)\n\n\ndef mid(row):\n check(isinstance(row, dict) and row.get(\"type\") == \"movie\", \"Unexpected non-movie row.\")\n m = row.get(\"movie\")\n check(isinstance(m, dict) and isinstance(m.get(\"ids\"), dict), \"Missing/null movie: stop, do not skip it.\")\n i = m[\"ids\"].get(\"trakt\")\n check(number(i), \"Invalid Trakt movie ID.\")\n return i\n\n\ndef validate(kind, rows):\n check(isinstance(rows, list), \"Expected a JSON array.\")\n seen = set()\n for r in rows:\n movie = mid(r)\n if kind == \"history\":\n key = r.get(\"id\")\n check(number(key), \"Invalid history ID; require an exact positive int64.\")\n date(r.get(\"watched_at\"))\n check(isinstance(r.get(\"action\"), str) and bool(r[\"action\"]), \"Missing history action.\")\n else:\n key = movie\n if kind == \"ratings\":\n check(type(r.get(\"rating\")) is int and 1 <= r[\"rating\"] <= 10, \"Invalid rating.\")\n date(r.get(\"rated_at\"))\n elif kind == \"watchlist\":\n date(r.get(\"listed_at\"))\n else:\n raise ValueError(\"Unexpected dataset.\")\n check(key not in seen, \"Duplicate ID: incomplete or changing snapshot.\")\n seen.add(key)\n return rows\n\n\ndef signature(r):\n return (mid(r), date(r[\"watched_at\"]).replace(second=0, microsecond=0).isoformat(), r[\"action\"])\n\n\ndef hist(rows):\n return {r[\"id\"]: signature(r) for r in rows}\n\n\ndef ratings(rows):\n return {mid(r): (r[\"rating\"], date(r[\"rated_at\"]).isoformat()) for r in rows}\n\n\ndef watchlist(rows):\n return {mid(r) for r in rows}\n\n\ndef label(value):\n check(bool(re.fullmatch(r\"[a-z][a-z0-9_-]{0,40}\", value)), \"Use a short lowercase snapshot name, for example before or after-add.\")\n return value\n\n\ndef parse_headers(raw):\n text = raw.decode(\"ascii\")\n check(\"\\r\" not in text.replace(\"\\r\\n\", \"\"), \"Use LF or CRLF header lines, not a bare carriage return.\")\n lines = text.replace(\"\\r\\n\", \"\\n\").split(\"\\n\")\n if lines and lines[-1] == \"\":\n lines.pop()\n check(lines and all(lines), \"Empty header lines are not accepted.\")\n headers = {}\n for line in lines:\n check(not any(ord(c) < 32 or ord(c) == 127 for c in line), \"Folded lines and control characters are not accepted.\")\n name, separator, value = line.partition(\":\")\n check(separator and re.fullmatch(r\"[A-Za-z0-9-]+\", name), \"Malformed local header file; use one complete header per line.\")\n key = name.lower()\n check(key not in headers, \"Duplicate header name in local file.\")\n value = value.strip(\" \")\n check(value and not any(ord(c) < 32 or ord(c) == 127 for c in value), \"Header values must be nonempty and contain no control characters.\")\n headers[key] = value\n check(set(headers) == {\"authorization\", \"trakt-api-key\", \"trakt-api-version\", \"content-type\", \"user-agent\"}, \"The local file must contain exactly the five header names listed in this guide and Trakt'"'"'s authentication reference.\")\n check(headers[\"trakt-api-version\"] == \"2\", \"The API version header must be 2.\")\n # The reader prepares all values using the official authentication reference.\n # This helper does not create, infer, inspect a scheme, or refresh credentials.\n return headers\n\n\ndef auth():\n raw = (ROOT / \"auth.headers\").read_bytes()\n return parse_headers(raw), sha(raw)\n\n\ndef init(headers_file):\n raw = Path(headers_file).expanduser().read_bytes()\n parse_headers(raw)\n ROOT.mkdir(exist_ok=True, mode=0o700)\n check(not (ROOT / \"auth.headers\").exists(), \"Credentials already exist; do not change accounts within a repair batch.\")\n ROOT.chmod(0o700)\n write_new(ROOT / \"auth.headers\", raw)\n (ROOT / \"auth.headers\").chmod(0o600)\n print(\"Imported your existing complete header file byte-for-byte into a private local working directory. No authentication value was created or displayed. Keep both local copies private; do not share this directory.\")\n\n\ndef get(path, headers):\n global LAST_GET\n delay = 0.65 - (time.monotonic() - LAST_GET)\n if delay > 0:\n time.sleep(delay)\n LAST_GET = time.monotonic()\n request = urllib.request.Request(API + path, headers=headers, method=\"GET\")\n # No retry and no redirect: do not forward credentials to another location.\n class NoRedirect(urllib.request.HTTPRedirectHandler):\n def redirect_request(self, req, fp, code, msg, response_headers, newurl):\n return None\n try:\n with urllib.request.build_opener(NoRedirect).open(request, timeout=45) as response:\n check(response.status == 200, \"GET did not return HTTP 200.\")\n return response.read(), {k.lower(): v for k, v in response.headers.items()}\n except urllib.error.HTTPError as exc:\n body = exc.read()\n public_headers = {k.lower(): v for k, v in exc.headers.items() if k.lower() in (\"retry-after\", \"date\", \"content-type\", \"x-request-id\") or k.lower().startswith(\"x-ratelimit\")}\n stem = \"get-error-\" + dt.datetime.now(dt.timezone.utc).strftime(\"%Y%m%dT%H%M%S%fZ\")\n write_new(ROOT / (stem + \"-body.bin\"), body)\n write_new(ROOT / (stem + \".json\"), encoded({\"method\": \"GET\", \"path\": path, \"status\": exc.code, \"response_headers\": public_headers, \"response_body\": stem + \"-body.bin\"}))\n retry = public_headers.get(\"retry-after\", \"not supplied\")\n raise ValueError(\"GET HTTP \" + str(exc.code) + \"; Retry-After: \" + retry + \". Saved response metadata/body at \" + str(ROOT / stem) + \". Snapshot stays INCOMPLETE. No automatic retry.\") from None\n\n\ndef page_meta(headers, page):\n keys = (\"page\", \"page-count\", \"item-count\", \"limit\")\n check(all(\"x-pagination-\" + k in headers for k in keys), \"Pagination headers missing: completeness is unproved, so stop.\")\n d = {k: int(headers[\"x-pagination-\" + k]) for k in keys}\n check(d[\"page\"] == page and d[\"limit\"] > 0 and d[\"item-count\"] >= 0, \"Invalid pagination metadata.\")\n if d[\"item-count\"] == 0:\n check(d[\"page-count\"] in (0, 1) and page == 1, \"Invalid empty-list pagination.\")\n else:\n check(d[\"page-count\"] == (d[\"item-count\"] + d[\"limit\"] - 1) // d[\"limit\"], \"Inconsistent page count.\")\n return d\n\n\ndef collect(kind, endpoint, destination, headers, fetcher=get):\n rawdir = destination / (kind + \"-raw\")\n rawdir.mkdir()\n all_rows, pages, stamp, first = [], [], None, None\n p, limit = 1, 100\n while True:\n path = endpoint + \"?\" + urllib.parse.urlencode({\"page\": p, \"limit\": limit})\n body, response_headers = fetcher(path, headers)\n name = \"page-%04d.json\" % p\n write_new(rawdir / name, body)\n meta = page_meta(response_headers, p)\n current = (meta[\"page-count\"], meta[\"item-count\"], meta[\"limit\"])\n stamp = current if stamp is None else stamp\n check(stamp == current, \"Dataset changed during pagination.\")\n rows = validate(kind, json.loads(body))\n count = max(0, min(meta[\"limit\"], meta[\"item-count\"] - (p - 1) * meta[\"limit\"]))\n check(len(rows) == count, \"Short page: the snapshot is incomplete.\")\n first = rows if first is None else first\n all_rows.extend(rows)\n pages.append({\"file\": name, \"sha256\": sha(body), \"pagination\": meta})\n if p >= max(1, meta[\"page-count\"]):\n break\n p, limit = p + 1, meta[\"limit\"]\n validate(kind, all_rows)\n check(len(all_rows) == stamp[1], \"Wrong total row count.\")\n body, response_headers = fetcher(endpoint + \"?\" + urllib.parse.urlencode({\"page\": 1, \"limit\": stamp[2]}), headers)\n write_new(rawdir / \"first-page-recheck.json\", body)\n final_meta = page_meta(response_headers, 1)\n check(tuple(final_meta[k] for k in (\"page-count\", \"item-count\", \"limit\")) == stamp and validate(kind, json.loads(body)) == first, \"First page or pagination changed: pause other writers and fetch again using a NEW snapshot name.\")\n data = encoded(all_rows)\n write_new(destination / (kind + \".json\"), data)\n return {\"endpoint\": endpoint, \"total\": len(all_rows), \"pages\": pages, \"first_page_recheck_sha256\": sha(body), \"sha256\": sha(data)}\n\n\ndef fetch(name):\n name = label(name)\n headers, auth_hash = auth()\n destination = ROOT / name\n destination.mkdir()\n write_new(destination / \"INCOMPLETE\", b\"Do not use this snapshot until manifest.json is complete.\\n\")\n manifest = {\"version\": 1, \"started_at\": now(), \"auth_sha256\": auth_hash, \"datasets\": {}}\n for kind, endpoint in ENDPOINTS.items():\n print(\"Fetching \" + kind + \"...\")\n manifest[\"datasets\"][kind] = collect(kind, endpoint, destination, headers)\n manifest.update({\"finished_at\": now(), \"complete\": True})\n write_new(destination / \"manifest.json\", encoded(manifest))\n (destination / \"INCOMPLETE\").unlink()\n print(\"Complete read-only snapshot: \" + str(destination) + \". Raw JSON and pagination metadata retained.\")\n\n\ndef snapshot(name):\n destination = ROOT / label(name)\n check(not (destination / \"INCOMPLETE\").exists(), \"Incomplete snapshot; no plan may use it.\")\n manifest_path = destination / \"manifest.json\"\n manifest = read_json(manifest_path)\n check(manifest.get(\"complete\") is True and manifest.get(\"version\") == 1, \"Invalid snapshot manifest.\")\n check(manifest[\"auth_sha256\"] == auth()[1], \"Credentials changed since this snapshot; use one account/token per batch.\")\n result = {\"name\": name, \"manifest_sha256\": sha(manifest_path.read_bytes())}\n for kind, endpoint in ENDPOINTS.items():\n metadata = manifest[\"datasets\"][kind]\n check(metadata[\"endpoint\"] == endpoint, \"Wrong source endpoint.\")\n body = (destination / (kind + \".json\")).read_bytes()\n check(sha(body) == metadata[\"sha256\"], \"Snapshot file was changed.\")\n rows = validate(kind, json.loads(body))\n check(len(rows) == metadata[\"total\"], \"Snapshot row count mismatch.\")\n raw_rows = []\n for page in metadata[\"pages\"]:\n raw = (destination / (kind + \"-raw\") / page[\"file\"]).read_bytes()\n check(sha(raw) == page[\"sha256\"], \"Raw page was changed.\")\n raw_rows.extend(json.loads(raw))\n check(raw_rows == rows, \"Combined snapshot differs from raw responses.\")\n raw = (destination / (kind + \"-raw\") / \"first-page-recheck.json\").read_bytes()\n check(sha(raw) == metadata[\"first_page_recheck_sha256\"], \"Raw recheck was changed.\")\n result[kind] = rows\n return result\n\n\ndef preview(name):\n s = snapshot(name)\n check(s[\"history\"], \"No movie history to repair.\")\n out = io.StringIO(newline=\"\")\n writer = csv.writer(out)\n writer.writerow([\"choose\", \"history_id\", \"movie_id\", \"title\", \"year\", \"watched_at\", \"unknown\"])\n for r in s[\"history\"]:\n m = r[\"movie\"]\n writer.writerow([\"\", \"h:\" + str(r[\"id\"]), \"m:\" + str(mid(r)), \"t:\" + str(m.get(\"title\", \"\")), m.get(\"year\"), \"at:\" + r[\"watched_at\"], \"YES\" if date(r[\"watched_at\"]) == EPOCH else \"NO\"])\n path = ROOT / (name + \"-review.csv\")\n write_new(path, (\"\\ufeff\" + out.getvalue()).encode(\"utf-8\"))\n print(\"Review \" + str(path) + \". Put exact YES only in choose for plays you personally identify as false dates. Leave all other cells unchanged. h:, m:, t:, at: keep spreadsheet cells as text.\")\n\n\ndef select(s, path):\n raw = path.read_bytes()\n choices = list(csv.DictReader(io.StringIO(raw.decode(\"utf-8-sig\"))))\n check(choices and all(c.get(\"choose\") in (\"\", \"YES\") for c in choices), \"choose must be blank or exact YES.\")\n by_id = {\"h:\" + str(r[\"id\"]): r for r in s[\"history\"]}\n unknown = {mid(r) for r in s[\"history\"] if date(r[\"watched_at\"]) == EPOCH}\n selected = []\n for c in choices:\n if c[\"choose\"] != \"YES\":\n continue\n r = by_id.get(c.get(\"history_id\"))\n check(r is not None, \"Selected history ID is missing or changed; retain h:.\")\n check(c.get(\"movie_id\") == \"m:\" + str(mid(r)), \"Movie/history mismatch; retain m:.\")\n check(c.get(\"title\") == \"t:\" + str(r[\"movie\"].get(\"title\", \"\")) and c.get(\"watched_at\") == \"at:\" + r[\"watched_at\"], \"Selected title/date cell was changed; recheck the CSV.\")\n check(mid(r) not in unknown, \"Selected movie already has an Unknown play; this workflow stops.\")\n selected.append(r)\n check(selected and len({mid(r) for r in selected}) == len(selected), \"Select exactly one false play per selected movie, and at least one movie.\")\n return selected, sha(raw)\n\n\ndef plan(name, review):\n check(not (ROOT / \"plan.json\").exists() and not (ROOT / \"add.json\").exists(), \"This working directory already has a plan; do not overwrite a repair batch.\")\n s = snapshot(name)\n selected, selection_hash = select(s, Path(review))\n for r in selected:\n print(json.dumps({\"history_id\": \"h:\" + str(r[\"id\"]), \"movie_id\": \"m:\" + str(mid(r)), \"title\": r[\"movie\"].get(\"title\"), \"old_date\": r[\"watched_at\"], \"new_date\": \"Unknown\"}, ensure_ascii=False))\n affected = watchlist(s[\"watchlist\"]) & {mid(r) for r in selected}\n accepted = False\n if affected:\n print(\"These selected movie IDs are on your Watchlist and marking watched may remove them: \" + \", \".join(\"m:\" + str(i) for i in sorted(affected)))\n check(input(\"Accept those Watchlist removals? Type YES, REMOVE FROM WATCHLIST: \") == \"YES, REMOVE FROM WATCHLIST\", \"Watchlist removal not accepted; no plan written.\")\n accepted = True\n check(input(\"Confirm only the selected false-date plays above. Type YES: \") == \"YES\", \"No plan written.\")\n review_bytes = Path(review).read_bytes()\n check(sha(review_bytes) == selection_hash, \"The selected CSV changed during confirmation; no plan written.\")\n addition = {\"movies\": [{\"ids\": {\"trakt\": mid(r)}, \"watched_at\": \"unknown\"} for r in selected]}\n p = {\"version\": 1, \"created_at\": now(), \"before\": name, \"before_manifest_sha256\": s[\"manifest_sha256\"], \"auth_sha256\": auth()[1], \"selection_sha256\": selection_hash, \"selected_history_ids\": [r[\"id\"] for r in selected], \"watchlist_accepted\": accepted, \"add_sha256\": sha(encoded(addition))}\n write_new(ROOT / \"selected-review.csv\", review_bytes)\n write_new(ROOT / \"plan.json\", encoded(p))\n write_new(ROOT / \"add.json\", encoded(addition))\n print(\"Created plan.json and add.json. No API change made. No old-play removal file exists yet. Inspect both files before the separate ADD request.\")\n\n\ndef load_plan():\n p = read_json(ROOT / \"plan.json\")\n check(p.get(\"version\") == 1 and p[\"auth_sha256\"] == auth()[1], \"Plan/authentication mismatch.\")\n s = snapshot(p[\"before\"])\n check(p[\"before_manifest_sha256\"] == s[\"manifest_sha256\"], \"The plan'"'"'s baseline was changed.\")\n by_id = {r[\"id\"]: r for r in s[\"history\"]}\n ids = p[\"selected_history_ids\"]\n check(isinstance(ids, list) and ids and all(number(i) and i in by_id for i in ids), \"Invalid selected history IDs.\")\n selected = [by_id[i] for i in ids]\n saved_selection = ROOT / \"selected-review.csv\"\n check(sha(saved_selection.read_bytes()) == p[\"selection_sha256\"], \"Saved selected CSV changed.\")\n selected_again, selection_hash = select(s, saved_selection)\n check([r[\"id\"] for r in selected_again] == ids, \"Plan history IDs differ from the exact saved CSV selection.\")\n wanted = {mid(r) for r in selected}\n check(len(wanted) == len(selected), \"More than one selected play per movie.\")\n check(not any(mid(r) in wanted and date(r[\"watched_at\"]) == EPOCH for r in s[\"history\"]), \"Baseline contains a preexisting Unknown for a selected movie.\")\n check(not watchlist(s[\"watchlist\"]) & wanted or p[\"watchlist_accepted\"] is True, \"Watchlist acceptance is absent.\")\n addition = {\"movies\": [{\"ids\": {\"trakt\": mid(r)}, \"watched_at\": \"unknown\"} for r in selected]}\n check(sha((ROOT / \"add.json\").read_bytes()) == p[\"add_sha256\"] == sha(encoded(addition)), \"ADD request differs from the bound plan.\")\n return p, s, selected, sha((ROOT / \"plan.json\").read_bytes())\n\n\ndef common(before, current, wanted, accepted):\n check(ratings(before[\"ratings\"]) == ratings(current[\"ratings\"]), \"Movie ratings or rating timestamps changed; stop.\")\n old_w, new_w = watchlist(before[\"watchlist\"]), watchlist(current[\"watchlist\"])\n allowed = old_w & wanted if accepted else set()\n check(new_w <= old_w and old_w - new_w <= allowed, \"Unexpected movie Watchlist membership change; stop.\")\n\n\ndef added_state(p, before, selected, current):\n check(current[\"name\"] != before[\"name\"], \"Use a NEW snapshot taken after the ADD request.\")\n old, new = hist(before[\"history\"]), hist(current[\"history\"])\n wanted = {mid(r) for r in selected}\n check(set(old) <= set(new) and all(new[i] == old[i] for i in old), \"An original play is missing or changed; no removal request generated.\")\n common(before, current, wanted, p[\"watchlist_accepted\"])\n added = [r for r in current[\"history\"] if r[\"id\"] not in old]\n added_m = {mid(r) for r in added}\n check(added_m <= wanted and len(added_m) == len(added) and all(date(r[\"watched_at\"]) == EPOCH for r in added), \"Unexpected new plays or duplicate Unknowns; no removal request generated.\")\n return added, wanted\n\n\ndef verify_add(name):\n p, before, selected, plan_hash = load_plan()\n current = snapshot(name)\n added, wanted = added_state(p, before, selected, current)\n added_m = {mid(r) for r in added}\n if added_m != wanted:\n report = {\"plan_sha256\": plan_hash, \"snapshot\": name, \"snapshot_manifest_sha256\": current[\"manifest_sha256\"], \"new_unknown_ids\": [r[\"id\"] for r in added], \"missing_movie_ids\": sorted(wanted - added_m)}\n write_new(ROOT / (\"add-incomplete-\" + name + \".json\"), encoded(report))\n raise ValueError(\"ADD is only partly observed (or no new play is observed). Original plays remain. Do NOT resend ADD and do NOT remove originals. Keep this report; fetch a later NEW snapshot and re-run verify-add. To abandon the attempt after requests have settled, use prepare-undo-add on a fresh snapshot. Watchlist removals are not restored by undoing new plays.\")\n removal = {\"ids\": [r[\"id\"] for r in selected]}\n certificate = {\"plan_sha256\": plan_hash, \"after_add\": name, \"after_add_manifest_sha256\": current[\"manifest_sha256\"], \"unknown_plays\": added, \"remove_sha256\": sha(encoded(removal))}\n certificate_path = ROOT / \"add-verified.json\"\n if certificate_path.exists():\n saved = read_json(certificate_path)\n check(all(saved.get(k) == v for k, v in certificate.items()), \"Existing ADD certificate belongs to different evidence; do not overwrite it.\")\n else:\n check(not (ROOT / \"remove.json\").exists(), \"An unbound REMOVE file already exists; stop.\")\n certificate[\"verified_at\"] = now()\n write_new(certificate_path, encoded(certificate))\n write_same(ROOT / \"remove.json\", encoded(removal))\n print(\"ADD verified: every original play remains unchanged to its movie/date-minute/action, ratings are unchanged, and each target has exactly one new Unknown. Created remove.json containing only selected ORIGINAL history IDs. Inspect it before the separate REMOVE request.\")\n\n\ndef verify_final(name):\n p, before, selected, plan_hash = load_plan()\n certificate = read_json(ROOT / \"add-verified.json\")\n check(certificate[\"plan_sha256\"] == plan_hash, \"ADD verification is bound to a different plan.\")\n after_add = snapshot(certificate[\"after_add\"])\n check(certificate[\"after_add_manifest_sha256\"] == after_add[\"manifest_sha256\"], \"Verified ADD snapshot changed.\")\n actual_added, wanted = added_state(p, before, selected, after_add)\n check({mid(r) for r in actual_added} == wanted and certificate[\"unknown_plays\"] == actual_added, \"ADD certificate does not match the bound raw snapshot.\")\n removal = {\"ids\": [r[\"id\"] for r in selected]}\n check(sha((ROOT / \"remove.json\").read_bytes()) == certificate[\"remove_sha256\"] == sha(encoded(removal)), \"REMOVE request changed.\")\n current = snapshot(name)\n check(name not in (before[\"name\"], after_add[\"name\"]), \"Use a NEW snapshot taken after the REMOVE request.\")\n removed = {r[\"id\"] for r in selected}\n unknown = certificate[\"unknown_plays\"]\n validate(\"history\", unknown)\n expected = {i: sig for i, sig in hist(before[\"history\"]).items() if i not in removed}\n expected.update(hist(unknown))\n actual = hist(current[\"history\"])\n allowed_originals = {r[\"id\"]: signature(r) for r in selected}\n check(set(expected) <= set(actual) and all(actual[i] == expected[i] for i in expected), \"A retained or newly verified play is missing/changed; stop.\")\n remaining = set(actual) - set(expected)\n check(remaining <= removed and all(actual[i] == allowed_originals[i] for i in remaining), \"Unexpected final history change; stop.\")\n check(ratings(before[\"ratings\"]) == ratings(current[\"ratings\"]), \"Movie ratings or rating timestamps changed; stop.\")\n check(watchlist(after_add[\"watchlist\"]) == watchlist(current[\"watchlist\"]), \"Movie Watchlist membership changed during removal; stop.\")\n if remaining:\n path = ROOT / (\"remaining-remove-\" + name + \".json\")\n write_new(path, encoded({\"ids\": sorted(remaining)}))\n raise ValueError(\"REMOVE is incomplete. Fresh snapshot confirms only these selected original IDs remain; \" + str(path) + \" contains ONLY those IDs. Inspect it before any explicit retry of REMOVE; never resend ADD. Then fetch and verify a NEW final snapshot.\")\n report = {\"plan_sha256\": plan_hash, \"final_snapshot\": name, \"final_manifest_sha256\": current[\"manifest_sha256\"], \"verified_at\": now(), \"condition\": \"H0 minus S plus verified U; movie ratings unchanged; Watchlist membership unchanged since verified ADD\"}\n write_new(ROOT / (\"final-verified-\" + name + \".json\"), encoded(report))\n print(\"FINAL VERIFIED: original history minus only selected false-date plays plus their verified Unknown replacements. Existing real rewatches retained; movie ratings unchanged. Watchlist acceptance, if any, still applies.\")\n\n\ndef prepare_undo(name):\n p, before, selected, plan_hash = load_plan()\n current = snapshot(name)\n added, wanted = added_state(p, before, selected, current)\n check(added, \"No new Unknown plays observed to undo. Do not issue an empty removal request.\")\n payload = {\"ids\": [r[\"id\"] for r in added]}\n path = ROOT / (\"undo-add-\" + name + \".json\")\n write_new(path, encoded(payload))\n report = {\"plan_sha256\": plan_hash, \"snapshot\": name, \"snapshot_manifest_sha256\": current[\"manifest_sha256\"], \"payload_sha256\": sha(encoded(payload)), \"new_unknown_ids\": payload[\"ids\"]}\n write_new(ROOT / (\"undo-plan-\" + name + \".json\"), encoded(report))\n print(\"Optional abandonment request: \" + str(path) + \" removes ONLY new Unknown plays verified against the baseline. All original plays still exist. Inspect it, then use a separate explicit REMOVE request. This does not restore removed Watchlist membership. Afterward fetch a NEW snapshot and run verify-undo.\")\n\n\ndef verify_undo(name):\n p, before, selected, plan_hash = load_plan()\n current = snapshot(name)\n check(name != before[\"name\"], \"Use a NEW snapshot after the undo request.\")\n check(hist(before[\"history\"]) == hist(current[\"history\"]), \"History is not restored to the original IDs/movie/date-minute/action; stop.\")\n common(before, current, {mid(r) for r in selected}, p[\"watchlist_accepted\"])\n report = {\"plan_sha256\": plan_hash, \"snapshot\": name, \"snapshot_manifest_sha256\": current[\"manifest_sha256\"], \"verified_at\": now(), \"condition\": \"Original movie history and ratings restored; accepted Watchlist removals may remain\"}\n write_new(ROOT / (\"undo-verified-\" + name + \".json\"), encoded(report))\n print(\"UNDO VERIFIED: original movie history and ratings are present. Accepted Watchlist removals may remain. Abandon this batch; do not run its old add.json or remove.json. Use a fresh working directory for any later attempt.\")\n\n\ndef main():\n os.umask(0o077)\n parser = argparse.ArgumentParser(description=__doc__)\n sub = parser.add_subparsers(dest=\"command\", required=True)\n sub.add_parser(\"init\").add_argument(\"headers_file\")\n for command in (\"fetch\", \"preview\", \"verify-add\", \"verify-final\", \"prepare-undo-add\", \"verify-undo\"):\n sub.add_parser(command).add_argument(\"snapshot\")\n p = sub.add_parser(\"plan\")\n p.add_argument(\"snapshot\")\n p.add_argument(\"review_csv\")\n args = parser.parse_args()\n try:\n if args.command == \"init\":\n init(args.headers_file)\n elif args.command == \"fetch\":\n fetch(args.snapshot)\n elif args.command == \"preview\":\n preview(args.snapshot)\n elif args.command == \"plan\":\n plan(args.snapshot, args.review_csv)\n elif args.command == \"verify-add\":\n verify_add(args.snapshot)\n elif args.command == \"verify-final\":\n verify_final(args.snapshot)\n elif args.command == \"prepare-undo-add\":\n prepare_undo(args.snapshot)\n elif args.command == \"verify-undo\":\n verify_undo(args.snapshot)\n except (ValueError, KeyError, TypeError, OSError, csv.Error, urllib.error.HTTPError, urllib.error.URLError) as exc:\n print(\"STOP: \" + str(exc) + \"\\nNo mutation request was sent by this helper. Preserve existing files; do not overwrite snapshots or blindly repeat a POST.\", file=sys.stderr)\n raise SystemExit(2)\n\n\nif __name__ == \"__main__\":\n main()\n"; p.open("x",encoding="utf-8",newline="").write(source); hashlib.sha256(p.read_bytes()).hexdigest()=='"'"'21c8f1a918bd1b8d818476f57b2f7cab9ccfa56504da40fc1c586325d8aa2ded'"'"' or sys.exit("STOP: source SHA mismatch"); print("Complete source written locally. SHA-256: 21c8f1a918bd1b8d818476f57b2f7cab9ccfa56504da40fc1c586325d8aa2ded. Open and inspect trakt_repair.py before running it. No API request made.")'
소스 파일을 만드는 명령은 생성한 파일의 SHA-256을 출력합니다. 이 판에서 검토한 소스의 SHA-256은 21c8f1a918bd1b8d818476f57b2f7cab9ccfa56504da40fc1c586325d8aa2ded입니다. 표시된 값이 다르면 중단하고, 새로운 빈 작업 폴더에 전체 명령을 다시 복사하세요.