Technology · PRACTICAL GUIDE
Linux says “fork: Resource temporarily unavailable”? Prove the exhausted task budget first
Distinguish per-user, cgroup, systemd and kernel PID or thread ceilings before raising limits, killing processes or rebooting.
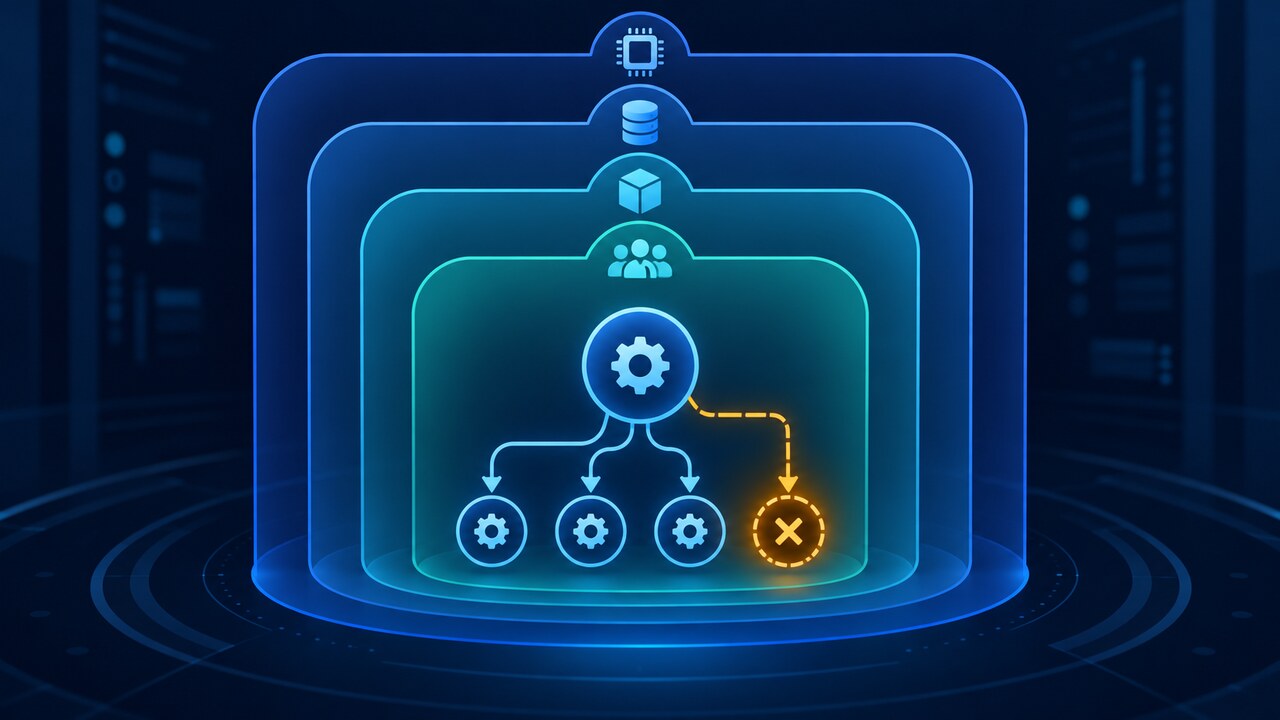
Linux can return EAGAIN from fork or clone even when free memory and file descriptors look healthy. The message is a task-budget failure, but the exhausted budget may belong to one user, one cgroup, one systemd unit or the host.
This audit preserves the evidence, identifies the governing boundary and the process or thread fan-out owner, then verifies the smallest reversible correction without turning a local incident into a global limit increase.
Freeze the failure before freeing tasks
Keep one recovery shell open and copy the exact command, timestamp, user, service or container, stderr and exit status before restarting anything. Record whether the failure says EAGAIN or ENOMEM. Linux fork(2) documents these separately, so a memory-looking symptom must not replace the actual errno.
Capture a short process and thread inventory from the same scope. Use ps fields such as PID, PPID, user, command and NLWP, and note recent deploys or traffic changes. Do not begin with a blanket kill: destroying the fan-out can erase the process tree and cgroup counters that identify the exhausted budget.
Test the per-user budget first
fork(2) lists RLIMIT_NPROC as one EAGAIN cause. The limit applies to processes and, on Linux, more precisely to threads for the real user ID. Compare the failing process real UID with its soft and hard limit, then count that UID’s live threads rather than counting only process rows.
A high shell ulimit is not proof that the service has the same effective limit. Capture limits from the failing process context or its service manager, and separate the service account from the operator who is inspecting it. If the count is near the effective ceiling, identify which executable and parent own the growth before changing the limit.
Locate the cgroup and read its PID ledger
The cgroup v2 pids controller counts task IDs, including individual threads. Identify the failing process cgroup, then read pids.current, pids.peak, pids.events and pids.max in that cgroup. A rising max event counter is durable evidence that fork or clone attempts crossed the configured boundary and returned EAGAIN.
For a systemd unit, compare TasksCurrent, TasksMax and EffectiveTasksMax. TasksMax maps to pids.max, while the effective value reflects tighter parent boundaries. Read the actual unit and cgroup instead of assuming a container, user slice or parent service has the same headroom as the host.
Check host-wide ceilings only after nearer limits
If per-user and cgroup evidence show headroom, inspect /proc/sys/kernel/threads-max and /proc/sys/kernel/pid_max alongside the host task count. fork(2) names both as EAGAIN causes. A large pid_max alone does not rule out threads-max, a user limit or a nested cgroup limit.
Keep this layer separate from file-descriptor limits. Raising nofile or closing sockets does not create PID or thread budget. Also record whether the caller uses SCHED_DEADLINE without reset-on-fork, another documented EAGAIN path, but do not treat that specialized case as the default explanation.
Find the fan-out owner and classify it
Sort processes by thread count and descendants, then inspect the leading parent, service and workload. Compare the current shape with a known healthy baseline. A single process with rapidly increasing NLWP suggests a thread leak; many short-lived children can point to retry storms, worker oversubscription or an upstream concurrency change.
Decide whether the load is legitimate concurrency or uncontrolled growth. Preserve logs, stack samples and the process tree before mitigation. A reboot or kill may restore capacity, but without the owner and growth pattern it only converts a diagnosable exhaustion into a recurring incident.
Apply the smallest reversible correction
Prefer stopping the leaking or runaway producer, reducing worker or retry concurrency, or correcting the service boundary that is demonstrably too low. Increase a limit only when the measured steady-state workload and a documented safety margin justify it. Avoid infinity and avoid changing all users when one unit or cgroup is responsible.
Write down the old value, the new value, the owner, the reason and the rollback command. If the change is in systemd, update the controlled unit configuration and reload through the normal path. If it is a cgroup or container boundary, change the source configuration instead of relying on an ephemeral runtime write.
Re-run the exact creation path and prove headroom
After mitigation, rerun the same command or controlled workload from the same user, unit and container. Confirm that a child is actually created, not merely that the error disappeared from one wrapper. Recheck the per-user thread count, cgroup pids.current versus pids.max, pids.events, and host ceilings.
Success means the exact fork or clone path works, the relevant event counter no longer rises, and task usage remains below the chosen boundary during an observation window. Keep the evidence and rollback plan with the incident. A successful reboot without these checks is recovery, not diagnosis.