Technology · PRACTICAL GUIDE
ENOSPC says the file-watcher limit is reached? Build an inotify consumer ledger before raising sysctl
On Linux, the same ENOSPC message can hide exhausted watch marks, exhausted inotify instances, a broad watch scope, or another process using the shared per-user pool. Inventory consumers first, then change one limit or exclusion with evidence.
An `ENOSPC: System limit for number of file watchers reached` error from a Linux development tool usually points to inotify resource exhaustion, not a full project directory or a broken package install. The name of the file in the error is often only the next path the application tried to register; it does not identify the process that consumed the shared allowance.
The limits are charged per real user ID, so an editor, language server, dev server, test runner, sync client and containerized process can compete for the same pool. A high `max_user_watches` value also does not rule out exhaustion of `max_user_instances`, while queue overflow is a third failure mode with different evidence.
Before raising a sysctl, restarting the machine or killing every watcher, build a read-only consumer ledger from `/proc`. Compare limits, inotify instances, watch marks, process identity, permission gaps and namespace context, then make one reversible change and measure again.
Confirm that this is the inotify ENOSPC branch
Capture the exact error, command, operating system and path. If the failure comes from `fs.watch`, Chokidar, Watchpack, an editor watcher or another Linux file-monitoring path, inotify exhaustion is a strong hypothesis. Do not treat every ENOSPC message as identical: check `df -h` and `df -i` when the failing operation is a file write rather than a watcher registration.
Record the affected real user ID with `id -ru` and the current values of `/proc/sys/fs/inotify/max_user_watches`, `max_user_instances` and `max_queued_events`. The first two can produce registration failures; queue overflow instead drops events and emits `IN_Q_OVERFLOW`, so raising a watch count does not repair a consumer that cannot drain its queue.
Count instances and watch marks separately
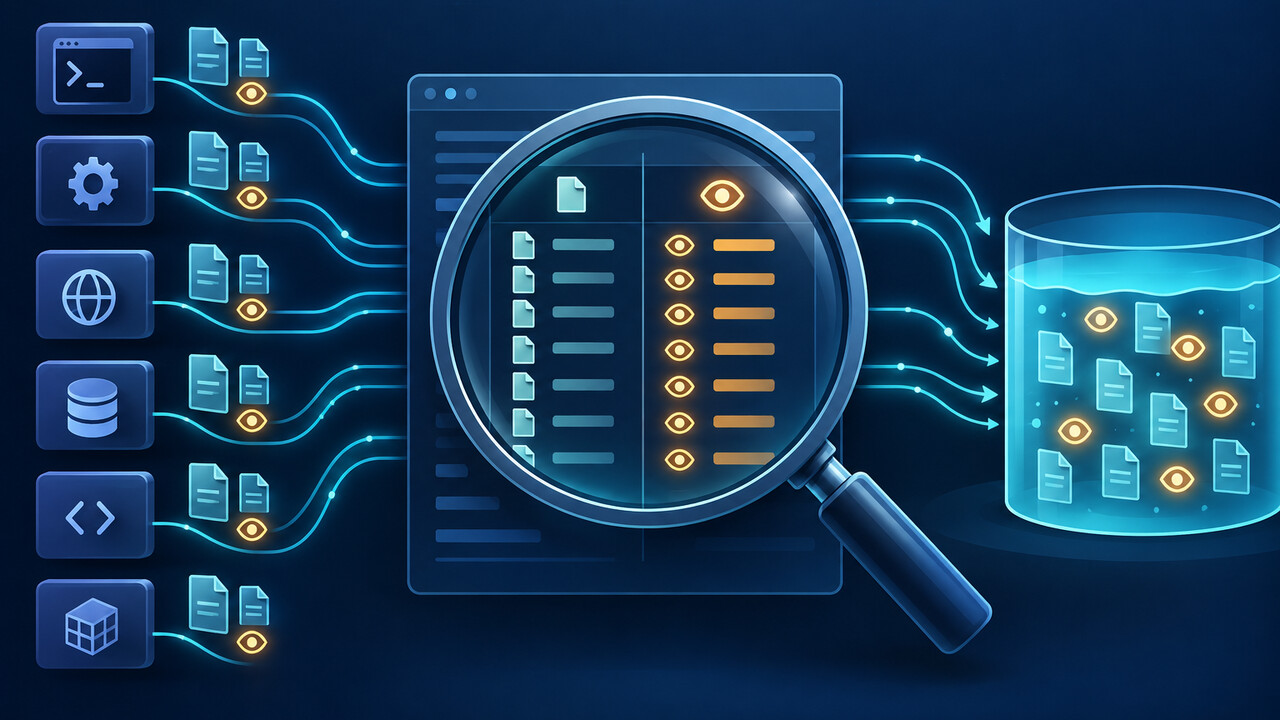
An inotify instance is represented by an `anon_inode:inotify` file descriptor. That descriptor can contain many watch marks. A quick count of matching descriptors tells you how many instances exist, but it does not tell you how close the user is to `max_user_watches`.
For each accessible `/proc/<pid>/fdinfo/<fd>` that belongs to an inotify descriptor, count lines beginning with `inotify`. Those lines are the watch descriptors documented by the kernel. Sum them per PID and per real UID, and keep the number of inotify descriptors as a separate `instances` column.
Build a permission-aware consumer ledger
For every PID you can inspect, record real UID, process name or command, inotify-instance count and watch-mark count. Use NUL-safe or field-safe parsing for command data, and never execute text read from `/proc/<pid>/cmdline`. If a process exits while you scan, mark it as raced rather than turning the disappearance into a zero.
Also count permission-denied or unreadable `fdinfo` entries. A ledger that sees only your own processes can still diagnose a per-user pool, but it cannot prove system-wide absence. On systems mounted with `hidepid`, inside containers or across PID namespaces, run the same read-only inventory in the namespace that owns the affected process or ask an administrator for an equivalent report.
Run the tested read-only ledger
Save the script below as `inotify-ledger.sh`, review it locally, then run `bash inotify-ledger.sh`. It reads procfs and sysctl files only. It does not call `sysctl -w`, kill a process, restart a service, delete a file or resolve private watched paths.
```bash #!/usr/bin/env bash set -u printf 'setting\tvalue\n' for name in max_user_watches max_user_instances max_queued_events; do path="/proc/sys/fs/inotify/${name}" if [[ -r "$path" ]]; then IFS= read -r value < "$path" printf '%s\t%s\n' "$name" "$value" else printf '%s\tUNREADABLE\n' "$name" fi done printf '\npid\truid\tcomm\tinstances\twatches\tunreadable_fdinfo\n' for proc in /proc/[0-9]*; do pid=${proc##*/} [[ -r "$proc/status" ]] || continue ruid=$(awk '/^Uid:/{print $2; exit}' "$proc/status" 2>/dev/null || true) [[ -n "$ruid" ]] || continue comm=$(tr '\t\n' ' ' < "$proc/comm" 2>/dev/null || true) instances=0 watches=0 unreadable=0 shopt -s nullglob for fdinfo in "$proc"/fdinfo/*; do fd=${fdinfo##*/} target=$(readlink "$proc/fd/$fd" 2>/dev/null || true) [[ "$target" == "anon_inode:inotify" ]] || continue ((instances+=1)) if [[ -r "$fdinfo" ]]; then count=$(awk '/^inotify /{n++} END{print n+0}' "$fdinfo" 2>/dev/null || printf '0') ((watches+=count)) else ((unreadable+=1)) fi done if ((instances > 0 || watches > 0 || unreadable > 0)); then printf '%s\t%s\t%s\t%s\t%s\t%s\n' "$pid" "$ruid" "$comm" "$instances" "$watches" "$unreadable" fi done | sort -t $'\t' -k5,5nr -k4,4nr printf '\nnamespace\ttarget\n' for ns in pid user mnt; do printf 'self_%s\t%s\n' "$ns" "$(readlink "/proc/self/ns/$ns" 2>/dev/null || printf 'UNREADABLE')" printf 'init_%s\t%s\n' "$ns" "$(readlink "/proc/1/ns/$ns" 2>/dev/null || printf 'UNREADABLE')" done ```
The isolated verification used one Node.js process that watched three distinct temporary directories. The ledger reported one inotify instance and three watch marks. The test host also preserved an unreadable PID 1 namespace result instead of presenting incomplete visibility as zero usage.
Do not confuse the failing path with the largest consumer
The path in the exception is the watch registration that hit the limit. The largest consumer may be another workspace, an extension host, a language server, a sync client or a long-lived dev process. GitHub issue reports show one editor extension using tens of thousands of marks while a separate `serve` command received the failures.
Sort the ledger by watch marks, then repeat it after closing one confirmed, nonessential consumer normally. A large drop links cause and effect. A reboot can clear the pool, but it erases the attribution evidence and does not show whether the same broad scope will return.
Audit watch scope before changing the ceiling
Map the top consumer to its configured roots and exclusions. Large generated trees such as `.venv`, build output, caches and dependency directories often provide little editing value. Official VS Code guidance explicitly recommends `files.watcherExclude` for large irrelevant folders before adjusting platform limits.
Do not assume a generic `node_modules` exclusion reaches every watcher. Editors, extensions, language servers, test runners and framework dev servers can each maintain independent subscriptions. Change the exclusion in the component that owns the marks, then confirm the ledger decreases and expected file-change behavior still works.
Raise one limit only when the ledger justifies it
If legitimate watch scope remains larger than `max_user_watches`, choose a measured value with memory headroom and apply it through the distribution's supported sysctl location. If instance count—not mark count—is exhausted, changing only `max_user_watches` cannot help. Preserve the previous value, configuration file and application versions so the change is reversible.
Avoid pasting a universal number into every host. VS Code documents 524,288 as a possible maximum and describes substantial worst-case memory use, but containers, small VMs and multi-user systems have different budgets. Confirm the effective value after `sysctl --system`, rerun the workload and compare both the ledger and memory use.
Use a branch matrix instead of repeating random fixes
When one PID dominates, narrow or update that consumer. When many expected consumers collectively exceed the mark ceiling, raise `max_user_watches` conservatively. When instance count is near `max_user_instances`, look for many watcher objects or process leaks. When the ledger is incomplete, resolve permissions or namespace visibility before concluding that usage is low.
If marks and instances are comfortably below their limits, reproduce with a minimal workspace and inspect the application's own watcher logs; the error may have been transient, namespace-specific or misclassified. Escalate with the before-and-after ledger, exact limits, kernel and application versions, and a minimal reproduction—never with secrets or a dump of private paths.