Technology · NEWS EXPLAINER
IBM Bob goes self-hosted: what stays on your OpenShift cluster—and what does not
IBM’s agentic development platform can now run its backend on customer-managed Red Hat OpenShift, including disconnected environments. The important buying question is not simply “on-prem or cloud,” but where model inference, logs and lifecycle responsibility actually sit.
IBM has made a self-hosted deployment of IBM Bob generally available, giving enterprises a way to run the backend of its agentic software-development platform on infrastructure they control. The option targets teams whose source code, regulated data or critical systems cannot be placed in a vendor-operated public service.
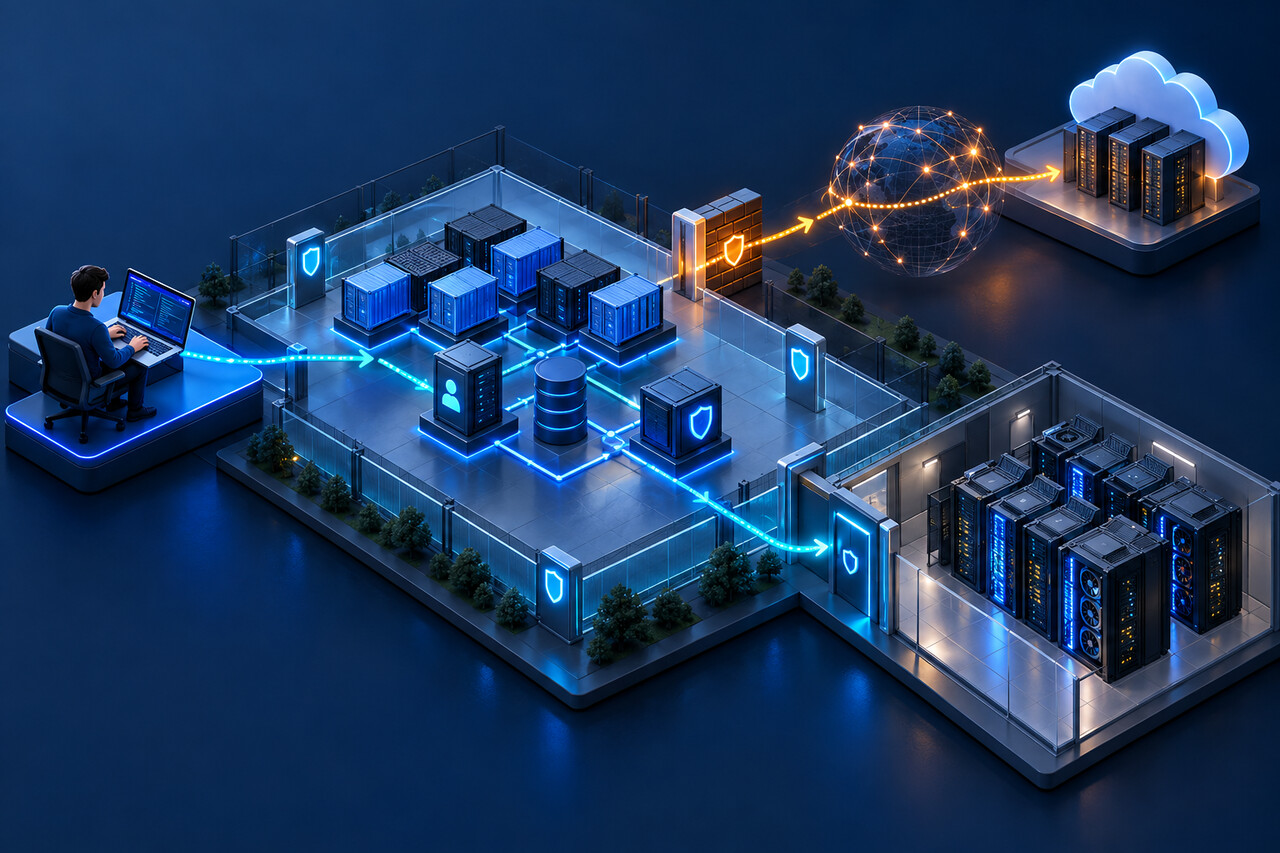
The word “self-hosted” does not settle where model inference happens. Bob’s backend, identity, audit logs and metering can run on customer-managed Red Hat OpenShift, while a hybrid configuration can still send prompts and code context to an approved external model service. A disconnected deployment instead requires a supported local model and customer-operated GPU capacity.
The practical decision is therefore architectural and operational: buyers must trace the exact model route and be ready to own OpenShift capacity, upgrades, availability, networking, storage, identity, platform logging, backups and incident response.
What runs inside the customer environment
IBM documents Bob self-hosted as a namespaced workload on Red Hat OpenShift. The deployment includes the Bob backend, inference gateway, identity, audit logging and usage metering, managed through an operator. Separate operator and application namespaces can share an existing cluster when capacity is sufficient; a dedicated cluster is not mandatory. Developers continue using Bob IDE and bob-shell, while an internal endpoint and corporate identity integration are operated by the customer.
Hybrid inference is not the same as fully local inference
In the hybrid path, Bob connects to a frontier model through a cloud account controlled by the organization. The backend and logs remain on OpenShift, but model requests and the code context they carry go to that external service under the organization’s agreement. A network that requires every token and code fragment to stay inside must use the fully self-hosted path with a supported open-weight model on customer GPUs. IBM’s release materials name NVIDIA Nemotron 3 Ultra and Poolside Laguna S 2.1, but do not establish one universal GPU configuration.
The customer owns the operating burden
IBM’s documentation assigns customers responsibility for infrastructure, integrations and lifecycle operations, including scaling, availability, upgrades, networking, storage and identity controls. Security-event logging and monitoring are handled at the OpenShift platform level rather than supplied as a complete Bob function. The two-stage bobctl installation separates cluster-wide resources, which require cluster-admin or equivalent approval, from namespace deployment, but it does not remove the need for platform governance.
Prerequisites and air-gapped work
Published prerequisites include a valid entitlement, access to the release bundle and entitled images, a supported OpenShift cluster, an administrative workstation, compatible oc, Helm 3.14 or later, Bash, OpenSSL, cert-manager 1.14 or later, and enough compute, memory, storage and worker capacity. A model endpoint must already exist because Bob does not provision model-serving infrastructure. Air-gapped installation is supported by mirroring images to a private registry, which adds image review, registry maintenance, patching and local model-serving duties.
A practical proof-of-concept checklist
Before a pilot, decide whether code context must remain fully offline or may reach an approved cloud-model account; identify the OpenShift and private-registry owners; assign upgrades, backups and incident response; approve the model route and capacity budget; define source-code access boundaries; map identity and platform logs into the required SIEM; and choose a measurable pilot result. IBM says a single-node OpenShift installation can support a proof of concept, but production sizing still depends on model, context length and concurrency.
What remains unproven
The reviewed materials do not provide a simple public self-hosted price, one production hardware bill, a customer-independent compliance result or a neutral benchmark against the SaaS edition. Self-hosting gives the buyer more control, but does not itself prove that a deployment is cheaper, faster, compliant or free of external data flows. The sound next step is an architecture review that traces prompts, code context, logs, identities and administrative actions across the proposed model route.