Technology · PRACTICAL GUIDE
Google Takeout photos show today’s date? Audit EXIF and JSON matches before editing
Separate download timestamps, embedded tags and sidecar dates in a read-only pilot report; a filename match is not permission to rewrite metadata.
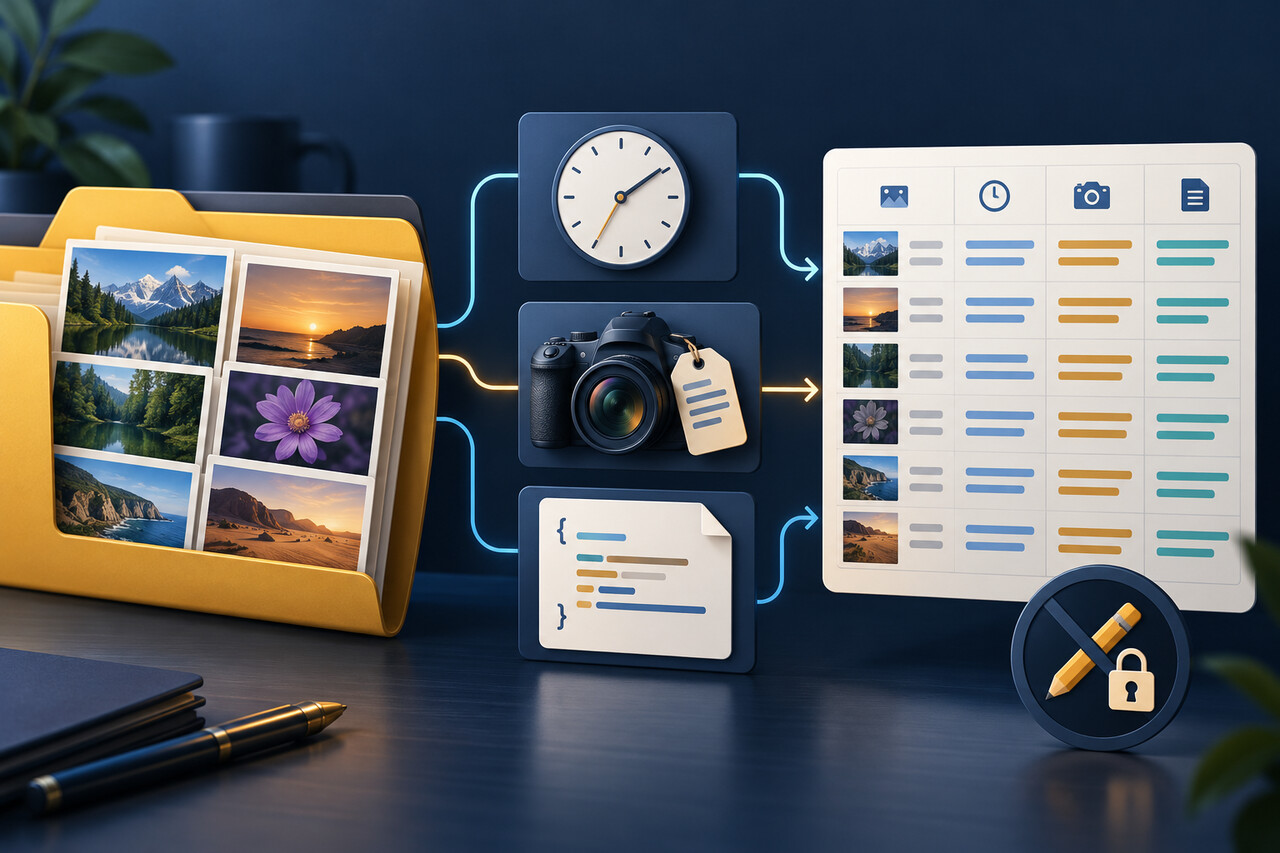
Google Takeout can leave several different date layers beside the same photo: a filesystem modification time assigned during download, embedded EXIF or video tags, and a JSON sidecar with fields such as photoTakenTime. They are not interchangeable. Google’s own help notes that an operating system may assign a new timestamp to a downloaded file while metadata remains available in file details.
The risky shortcut is to treat every file showing today’s date as damaged and immediately copy a JSON value into the media. Filename truncation, edited copies, duplicates and old versus supplemental-metadata naming can make more than one sidecar look plausible. A wrong one-to-one match can silently move thousands of photos to the wrong day.
This guide creates a bounded evidence table for a trusted extracted copy, then leaves every date comparison and metadata change for manual review. Missing metadata records are labeled not-inspected rather than treated as absent capture dates.
Preserve the export and read the embedded tags
Keep the original archives and finish extracting every part. Work on a trusted separate copy named Takeout, without symlinks, and keep report files outside that tree. This pilot supports at most 10,000 total source files; run on a small representative copy first. It hashes every source file twice, which can cost substantial disk reads, and scans candidate filenames conservatively rather than validating every possible Takeout layout.
Install ExifTool through its official distribution and Python 3.9 or later. From the parent folder, run the following read-only ExifTool template in Linux Bash. Use a fresh embedded.json, inspect stderr and the exit status, and stop on a read failure. This is tag export, not -json= import; no assignments, tagsFromFile or overwrite options are used. The ExifTool command was verified against its official reference but was not executed here.
( set -o noclobber; exiftool -r -json -G1 -s -DateTimeOriginal -CreateDate -OffsetTimeOriginal -OffsetTimeDigitized -Error -Warning "Takeout" > "embedded.json" )
Generate the bounded CSV report
With Takeout and embedded.json in the current folder, copy the next command as one line, retaining straight quotes and backslashes. It creates takeout-audit.csv outside the source tree with exclusive creation, so an existing report is refused. We executed the Python conversion through Linux Bash with synthetic metadata records; real ExifTool/media extraction and Windows/macOS execution were not tested.
The report inventories JPG/JPEG, HEIC, PNG, GIF, MP4, MOV, TIF/TIFF and WEBP extensions. It includes parsed raw embedded records, selected JSON date evidence and filesystem modification time labeled in UTC. It does not decode media or prove file validity. Source sizes, nanosecond mtimes, hashes and file set must remain unchanged before output creation; CSV header and every field are then read back and compared.
python3 -c 'exec("import csv, json, sys, hashlib\nfrom pathlib import Path\nfrom datetime import datetime, timezone\ndef pairs(items):\n result = {}\n for k, v in items:\n if k in result: raise ValueError('"'"'Duplicate JSON key'"'"')\n result[k] = v\n return result\ndef read_json(p):\n return json.loads(p.read_bytes().decode('"'"'utf-8-sig'"'"'), object_pairs_hook=pairs, parse_constant=lambda x: (_ for _ in ()).throw(ValueError('"'"'Nonstandard number'"'"')))\ndef utc(v):\n if not isinstance(v, dict) or '"'"'timestamp'"'"' not in v: return '"'"''"'"'\n t = v['"'"'timestamp'"'"']\n if type(t) is int: n = t\n elif isinstance(t, str) and t.lstrip('"'"'-'"'"').isdigit(): n = int(t)\n else: raise ValueError('"'"'Invalid epoch'"'"')\n return datetime.fromtimestamp(n, timezone.utc).isoformat()\nroot, metadata, output = map(Path, sys.argv[1:])\nroot = root.resolve()\nif not root.is_dir(): raise ValueError('"'"'Need extracted root directory'"'"')\nif output.resolve().is_relative_to(root): raise ValueError('"'"'Output must be outside source tree'"'"')\nfiles = sorted(p for p in root.rglob('"'"'*'"'"') if p.is_file())\nif len(files) > 10000: raise ValueError('"'"'Bounded pilot only: at most 10000 source files'"'"')\nif any(p.is_symlink() for p in root.rglob('"'"'*'"'"')): raise ValueError('"'"'Symlinks unsupported'"'"')\ndef digest(p):\n h = hashlib.sha256()\n with p.open('"'"'rb'"'"') as f:\n for chunk in iter(lambda: f.read(1048576), b'"'"''"'"'): h.update(chunk)\n return h.hexdigest()\ndef snapshot():\n return {str(p.relative_to(root)): (p.stat().st_size, p.stat().st_mtime_ns, digest(p)) for p in files}\nbefore = snapshot()\nmedia = [p for p in files if p.suffix.lower() in {'"'"'.jpg'"'"','"'"'.jpeg'"'"','"'"'.heic'"'"','"'"'.png'"'"','"'"'.gif'"'"','"'"'.mp4'"'"','"'"'.mov'"'"','"'"'.tif'"'"','"'"'.tiff'"'"','"'"'.webp'"'"'}]\nsidecars = [p for p in files if p.suffix.lower() == '"'"'.json'"'"']\ndata = read_json(metadata)\nif not isinstance(data, list): raise ValueError('"'"'Expected ExifTool JSON array'"'"')\nembedded = {}\nfor item in data:\n if not isinstance(item, dict) or not isinstance(item.get('"'"'SourceFile'"'"'), str): raise ValueError('"'"'Missing SourceFile'"'"')\n path = Path(item['"'"'SourceFile'"'"']).resolve()\n if not path.is_relative_to(root): raise ValueError('"'"'Metadata path outside root'"'"')\n if path in embedded: raise ValueError('"'"'Duplicate metadata row'"'"')\n embedded[path] = item\ncandidates = {}\nfor p in media:\n exact = [q for q in sidecars if q.parent == p.parent and q.name in (p.name+'"'"'.json'"'"', p.name+'"'"'.supplemental-metadata.json'"'"')]\n weak = [q for q in sidecars if q.parent == p.parent and q not in exact and len(q.name[:-5]) >= 5 and (p.name.startswith(q.name[:-5]) or q.name.startswith(p.name+'"'"'.s'"'"'))]\n candidates[p] = (exact, weak)\nused = {}\nfor p, (exact, weak) in candidates.items():\n for q in exact + weak: used[q] = used.get(q, 0) + 1\nrows = []\nfor p in media:\n exact, weak = candidates[p]; all_candidates = exact + weak\n state = '"'"'missing'"'"' if not all_candidates else '"'"'ambiguous-truncated'"'"' if weak else '"'"'ambiguous-duplicate'"'"' if len(exact) != 1 or used[exact[0]] != 1 else '"'"'unique'"'"'\n if '"'"'-edited'"'"' in p.stem.lower(): state = '"'"'edited-variant'"'"'\n evidence = []\n for q in all_candidates:\n try:\n value = read_json(q)\n if not isinstance(value, dict): raise ValueError('"'"'Sidecar is not object'"'"')\n evidence.append({'"'"'path'"'"':str(q.relative_to(root)), '"'"'photoTakenTimeUTC'"'"':utc(value.get('"'"'photoTakenTime'"'"')), '"'"'creationTimeUTC'"'"':utc(value.get('"'"'creationTime'"'"')), '"'"'title'"'"':value.get('"'"'title'"'"'), '"'"'error'"'"':'"'"''"'"'})\n except (ValueError, KeyError, OverflowError, OSError, UnicodeError) as e:\n evidence.append({'"'"'path'"'"':str(q.relative_to(root)), '"'"'error'"'"':type(e).__name__})\n state = '"'"'invalid-json'"'"'\n info = embedded.get(p)\n if info is None: embedded_status = '"'"'not-inspected'"'"'\n elif any(k.split('"'"':'"'"')[-1] in ('"'"'Error'"'"','"'"'Warning'"'"') for k in info): embedded_status = '"'"'read-warning-or-error'"'"'\n else: embedded_status = '"'"'record-present-not-capture-proof'"'"'\n rows.append([str(p.relative_to(root)),p.suffix.lower(),str(p.stat().st_size),datetime.fromtimestamp(p.stat().st_mtime,timezone.utc).isoformat(),embedded_status,json.dumps(info or {},ensure_ascii=False),json.dumps(evidence,ensure_ascii=False),state,'"'"'manual-comparison-required'"'"','"'"'No metadata write authorized'"'"'])\nif sorted(p for p in root.rglob('"'"'*'"'"') if p.is_file()) != files or snapshot() != before: raise ValueError('"'"'Source file set/byte/hash/mtime changed; no report created'"'"')\nheader = ['"'"'relative_media_path'"'"','"'"'media_type'"'"','"'"'size_bytes'"'"','"'"'filesystem_mtime_utc'"'"','"'"'embedded_read_status'"'"','"'"'embedded_tags_raw_json'"'"','"'"'candidate_date_evidence_json'"'"','"'"'sidecar_match_status'"'"','"'"'date_source_agreement'"'"','"'"'manual_review_reason'"'"']\nwith output.open('"'"'x'"'"',encoding='"'"'utf-8-sig'"'"',newline='"'"''"'"') as f:\n w=csv.writer(f);w.writerow(header);w.writerows(rows)\nwith output.open(encoding='"'"'utf-8-sig'"'"',newline='"'"''"'"') as f:\n if list(csv.reader(f)) != [header]+rows: raise ValueError('"'"'CSV readback mismatch'"'"')\nprint(len(media),'"'"'media rows; source bytes/hashes/mtimes unchanged; no metadata written'"'"')\n")' "Takeout" "embedded.json" "takeout-audit.csv"
Interpret matches and dates without guessing
The ten columns are relative_media_path, media_type, size_bytes, filesystem_mtime_utc, embedded_read_status, embedded_tags_raw_json, candidate_date_evidence_json, sidecar_match_status, date_source_agreement and manual_review_reason. Relative paths distinguish repeated filenames in separate folders. Raw embedded JSON retains available selected tags and offsets; a missing record is not-inspected, and a recorded warning/error is not a verified capture date.
Within the same directory, exact candidates are the full media filename plus .json or .supplemental-metadata.json. Weak candidates include a JSON basename of at least five characters that prefixes the media name, or shortened .s… suffix forms. All candidates and their parse errors remain visible. More than one exact candidate is ambiguous-duplicate; any weak candidate is ambiguous-truncated. A -edited filename is edited-variant, and invalid JSON/date data is invalid-json. Other naming variants can be missed: missing means no candidate under these rules, not proof that no sidecar exists.
Unique means one exact candidate not shared by another media row under these limited rules; it does not prove that its contents belong to that photo. JSON photoTakenTime and creationTime epochs are displayed separately in UTC. No field is selected as the correct capture date. Every row remains manual-comparison-required: an EXIF local time without a reliable zone cannot be compared as an exact instant. Preserve original text and review title, image content, album context and offsets before proposing a change.
Validate coverage and keep repair separate
The reported media count must equal the discovered files with the listed extensions; CSV record counts are not physical text-line counts because a field may contain a newline. Open a sample from each relevant branch: still image, video, edited item, duplicated name and non-ASCII filename. Inspect the actual file and sidecar together. Uninspected or erroring embedded records and weak, missing, edited or invalid candidates need manual review.
Import the CSV as UTF-8, comma-separated text with straight double quotes. Set every column to Text and avoid formula evaluation or trimming so filenames and raw evidence remain unchanged. Keep the JSON/CSV masters; annotate a working copy. If parsing, hashing, writing or readback fails, discard partial output, investigate the source and choose a new report name. This CSV is not an ExifTool import file and cannot update metadata.
Sixteen actual Linux Bash synthetic cases covered exact old/new names, missing and competing candidates, shared truncation, edited names, malformed/duplicate-key JSON, invalid epochs, Unicode/comma/newline paths, repeated basenames, uninspected video, read errors and empty exports. Sixteen additional overwrite attempts were refused; source bytes, hashes and mtimes stayed unchanged. No real archive, ExifTool, GUI or migration was tested. A later repair plan must identify an exact subset, source field, format-specific target tags, backup and rollback, then verify writes on copies. A folder sorting correctly alone is not proof of a correct migration.